
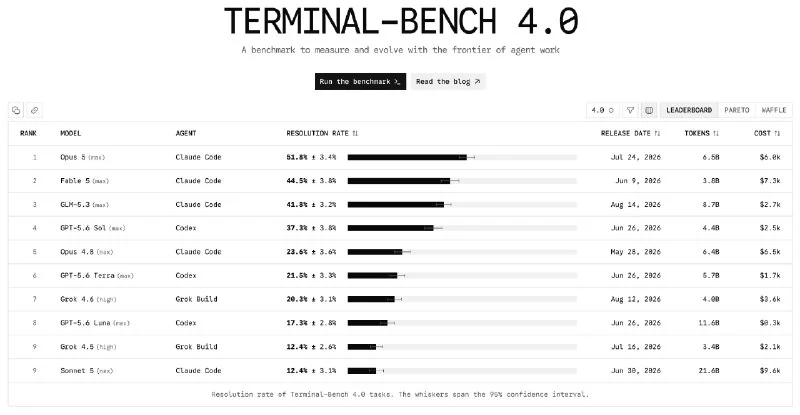
Terminal-Bench just shipped version 4.0, and it's already reshuffling the AI agent leaderboard. The update recalibrates how agent tasks are timed and resourced — CPU and memory included — while fixing 19 tasks and removing eight that suffered from saturation, refusals, leaked solutions, or quality problems. The maximum runtime for every task is now a uniform eight hours, an attempt to stop timeouts and environment quirks from derailing scores.
The new leaderboard has Opus 5 + Claude Code on top at 51.8%, with Fable 5 in second at 44.5%. But the real story is GLM-5.3: paired with Claude Code, it hit 41.8% to claim third place, edging past GPT-5.6 Sol + Codex at 37.3%. Notably, GLM-5.3 is the only model in the top three that doesn't come from Anthropic.
That's a serious jump from Terminal-Bench 3.0, where GLM-5.3 sat in fourth with 32.4%, behind GPT-5.6 Sol's 34.6%. Now, on 4.0, it's flipped the script — GLM-5.3 leads Sol by a solid 4.5 percentage points.