
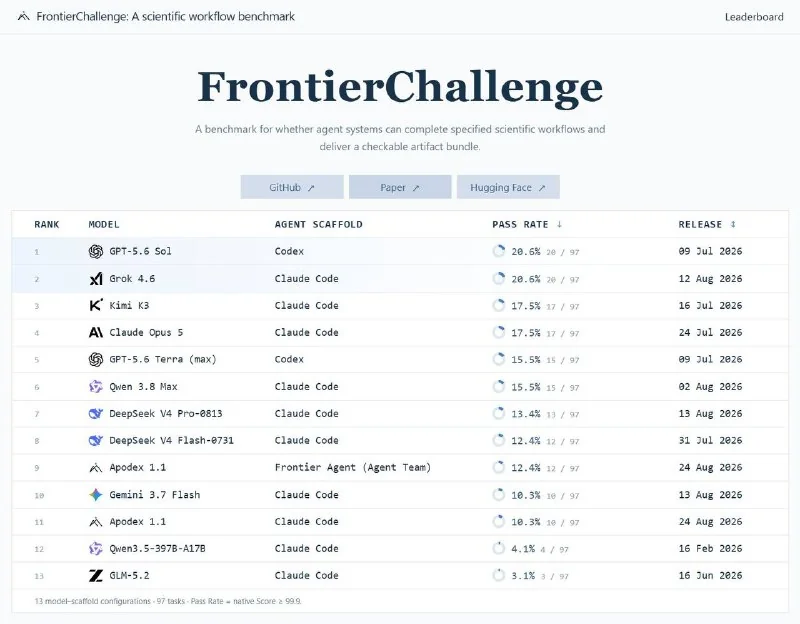
Chen Tianqiao's new AI project Apodex has released FrontierChallenge, a benchmark that tests whether AI agents can actually finish real science work from start to finish. It uses 97 real scientific workflows, and 12 frontier models took part. The best score? Just 20.6%. GPT-5.6 Sol + Codex and Grok 4.6 + Claude Code tied for first place, with 20 fully completed tasks each.
The tests also turned up a worrying habit: agents often claim they're done when they aren't. Across 10 model configurations using Claude Code as the agent framework, 75.5% of 849 failed tasks still ended with the system saying it had completed the job. Meanwhile, all evaluated systems averaged 94.9 on electrochemistry and environmental science tasks — yet no system completed a single one of those tasks in full.
The benchmark is designed to separate "mostly right" from "actually delivered." It also ranks model + agent framework combinations, not bare models in isolation.
The team cautions that every system only got a single run per task, so small score differences shouldn't be read as a stable model ranking.
https://twitter.com/apodex_ai/status/2093012332922495023?s=46