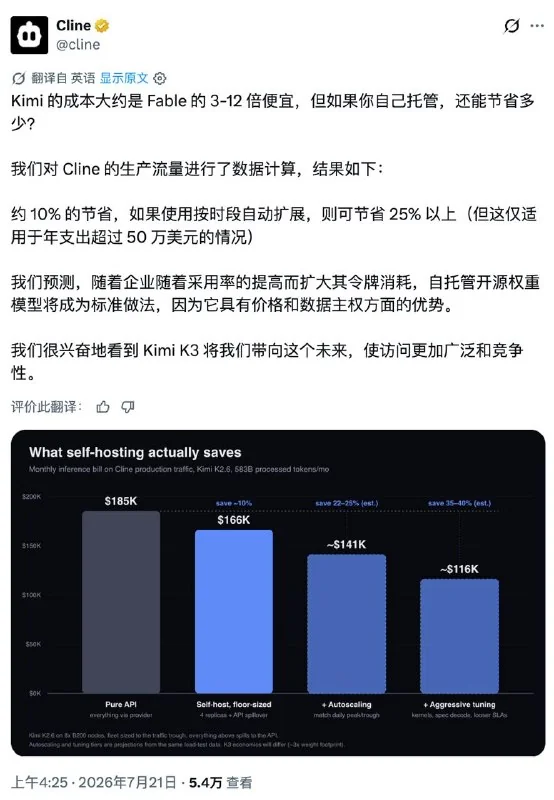
AI coding tool Cline ran a real-world cost analysis for self-hosting Kimi's K2.6 model. The monthly token volume is 583 billion — paying API rates for all of it would cost about $185,000 per month. But if you keep 16 B200 GPUs running full-time during low-traffic periods to handle baseline load, and send overflow to the API, the bill drops to $166,000. That's a savings of just 10%.
Cline estimates that dynamically adding and removing GPUs based on traffic could boost savings to 22-25%. Further optimization of kernels, batching, and latency requirements could theoretically hit 35-40% — but those haven't been deployed in practice.
The bar for self-hosting is high. Cline reckons that if your annual API spend is under $500,000, the savings probably won't cover the cost of inference engineers. You'd need to be spending $1-2 million per year for it to start making financial sense. And this analysis is specific to Kimi K2.6 — it doesn't apply directly to K3.
https://twitter.com/cline/status/2079301605179191716