
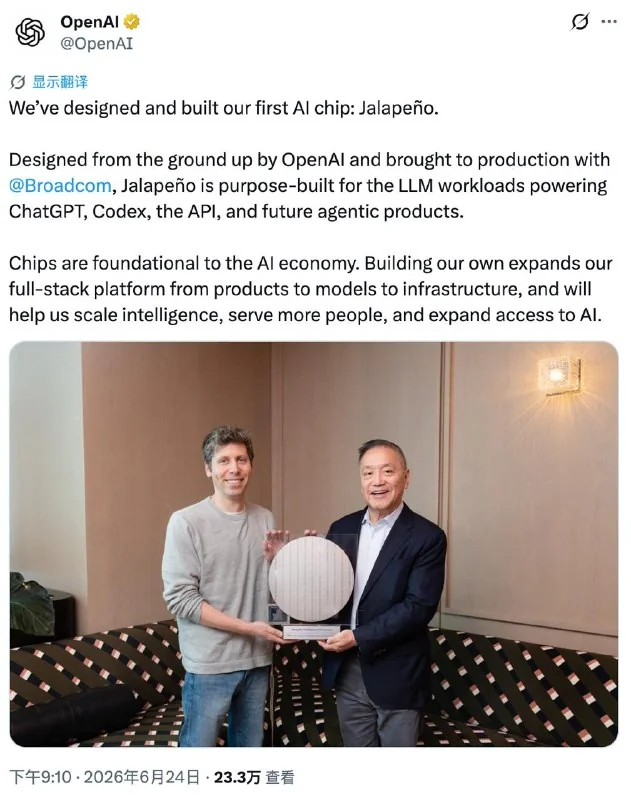
OpenAI has unveiled its first custom accelerator chip, Jalapeño, built specifically for large language model (LLM) inference. The company handled architecture and algorithm design, teaming up with Broadcom and Celestica to push the chip toward mass production. Jalapeño is meant to speed up ChatGPT, Codex, API calls, and future agent products while slashing compute costs.
Thanks to OpenAI’s own cutting-edge AI models lending a hand in design, Jalapeño went from initial concept to tape-out in just nine months — a record for advanced ASICs. The chip uses a co-designed algorithm and hardware approach, with custom LLM cores, revamped data movement, and a network architecture that squeezes out near-theoretical performance. Early engineering samples are already running GPT-5.3-Codex-Spark workloads at target frequency and power in the lab, and initial tests show walloping efficiency gains over existing top-tier hardware.
On the supply-chain side, Broadcom handled the silicon implementation and networking, integrating its Tomahawk chip into the design. Celestica provided board, rack, and system integration. As the first product in a multi-generation computing roadmap, Jalapeño is scheduled to begin large-scale deployment in gigawatt-level data centers — built with partners like Microsoft — by the end of 2026. The plan: expand OpenAI’s full-stack platform capabilities and drive down inference costs.