
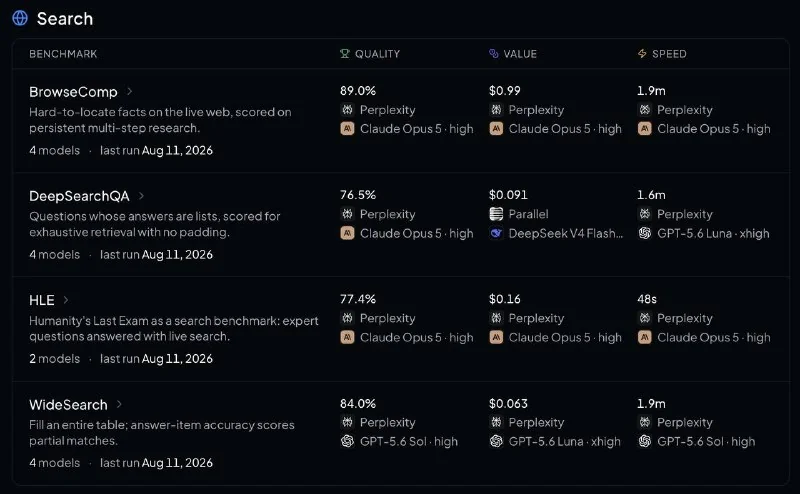
OpenRouter just launched a Web Search Benchmarks suite to answer a surprisingly practical question: how should you actually configure an AI model to search the web? The first batch puts Exa, Parallel, Perplexity, and models' built-in search through four benchmark sets, paired with GPT-5.6 Sol, Claude Opus 5, and DeepSeek V4 Flash, measuring accuracy, cost, and speed.
The headline finding: the number of search rounds you allow matters more than which search engine you pick. On hard tasks like BrowseComp, raising the search limit from 1 round to 25 roughly doubles the score, while per-question cost climbs about 2.5 to 7 times. Claude Opus 5 with Perplexity, for example, jumps from 35.8% at one round to 89.0% at 25.
The model itself matters more than the search provider, too. With everything else held fixed, swapping models moves scores by about 15 points on average; swapping between Exa, Parallel, and Perplexity moves them by about 10 points. A model vendor's own built-in search isn't automatically the best option, either — it depends on the task.
But searching more isn't always the smart buy. In BrowseComp, models that answered correctly averaged 10.3 searches, while models that got the answer wrong averaged 19.7 searches. For questions where the answer is genuinely hard to find, uncorking the search budget may just make the agent fail more expensively.
The full benchmark results are up on OpenRouter.