Meituan has open-sourced LongCat-2.0, a massive Mixture-of-Experts (MoE) model with 1.6 trillion total parameters and around 48 billion active parameters per token. It supports a 1-million-token context window.
This is the first trillion-parameter large language model to complete the entire training and inference pipeline using domestic computing power. It was pre-trained on over 50,000 domestic AI chips, processing 35 trillion tokens, proving the engineering stability of homegrown hardware for cutting-edge AI.
LongCat-2.0’s core improvements focus on long-context handling and inference efficiency. Its LongCat Sparse Attention (LSA) tackles the memory and compute overhead of sparse attention indices by introducing stream-aware indexing, cross-layer indexing, and hierarchical indexing. This makes index reads more continuous during long-text inference and allows reuse of index results between adjacent layers.
The model also integrates a 13.5-billion-parameter 5-gram embedding module, which expands the embedding space by modeling adjacent token combinations, enhancing local context representation. Compared to relying solely on MoE expert routing, this upfront embedding reduces some memory read/write pressure during large-batch inference.
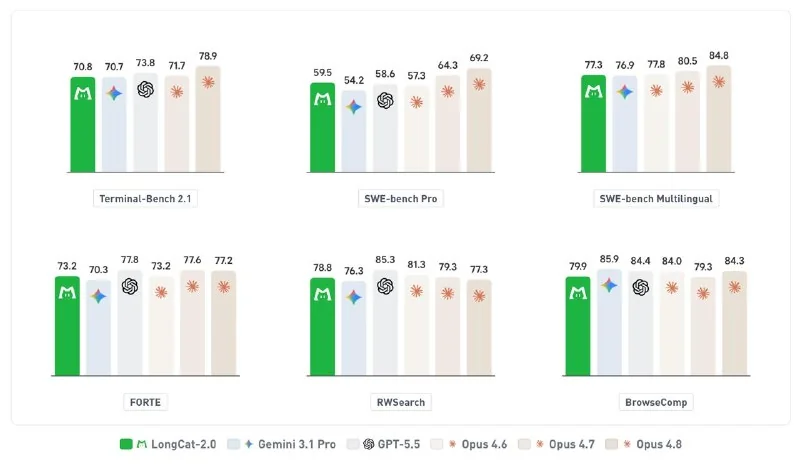
On benchmarks like SWE-bench Pro, SWE-bench Verified, and various agent and coding evaluations, LongCat-2.0 performs close to or even surpasses several mainstream closed-source models.