Ant Group’s Inclusion AI lab has released the model weights for Ling-2.6-flash, ending its API-only era. The model packs 104 billion total parameters, but thanks to a mixture of experts and a custom hybrid attention mechanism, it only fires up 7.4 billion per inference. Context window: 256K tokens. License: MIT. Three precision versions (BF16, FP8, INT4) are now on HuggingFace and ModelScope.

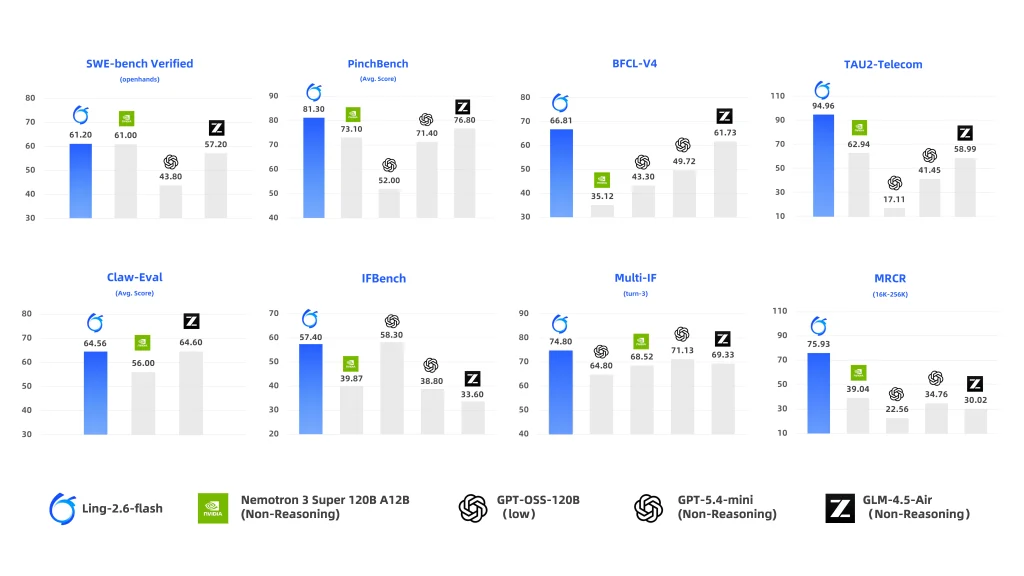
The architecture builds on Ling 2.0 by swapping out vanilla GQA for a 1:7 mixture of MLA (multi-head latent attention) and Lightning Linear layers, plus high-sparsity MoE. The result is inference speeds that make comparable models look pokey: on four H20 GPUs, Ling-2.6-flash hits 340 tokens per second generation, and its prefill and decode throughput peak at about 4x that of similarly sized open models. The benchmarks back it up: BFCL-V4, TAU2-bench, SWE-bench Verified (61.2%), Claw-Eval, and PinchBench all show near or at SOTA for its class. On Artificial Analysis’s full evaluation suite, the model consumed just 15 million total tokens. Math? AIME 2026 score: 73.85%.
The model’s efficiency is notable even next to other recent open-weight releases. DeepSeek’s V4 series also uses a hybrid architecture and pushes context to 1 million tokens, a different tradeoff for long-document work. Meanwhile, Inclusion AI has announced a trillion-parameter flagship, the Ling-2.6-1T, alongside a mini variant — but as of this writing, only the flash version’s weights are downloadable.