Ant Group's AI lab, Inclusion AI, just dropped Ling-2.6-1T — a new flagship instruction model with a trillion parameters that's less about slow deep thinking and more about getting stuff done fast. The company calls it "Fast-Thinking": a mechanism designed for precise task execution rather than long chains of reasoning.
According to Inclusion AI, Ling-2.6-1T is a significant upgrade over last year's Ling-1T, with general intelligence approaching GPT-5.4's non-reasoning mode. But the key difference is the output: it uses fewer tokens. The company is essentially making token efficiency the headline metric.
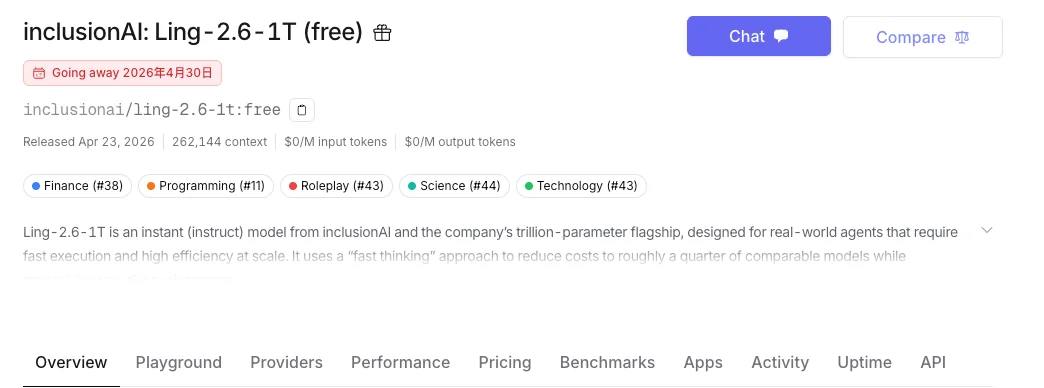
That makes it a natural fit for the agent era — code editing, tool calling, complex instruction following, and high-frequency production calls. The model is already listed on OpenRouter with a free API, supporting a 262.1k token context window and output up to 32.8k tokens.
Inclusion AI has also confirmed that Ling-2.6-1T will be open-sourced. This follows the recent release of Ling-2.6-flash, a smaller 104-billion-parameter model optimized for continuous agent workflows that previously appeared anonymously on OpenRouter under the name "Elephant Alpha." The trillion-parameter race is heating up: Xiaomi's AI lead recently revealed that the company's MiMo-V2-Pro model also packs a trillion parameters, calling that scale the minimum for competing with models like Claude Opus 4.6.