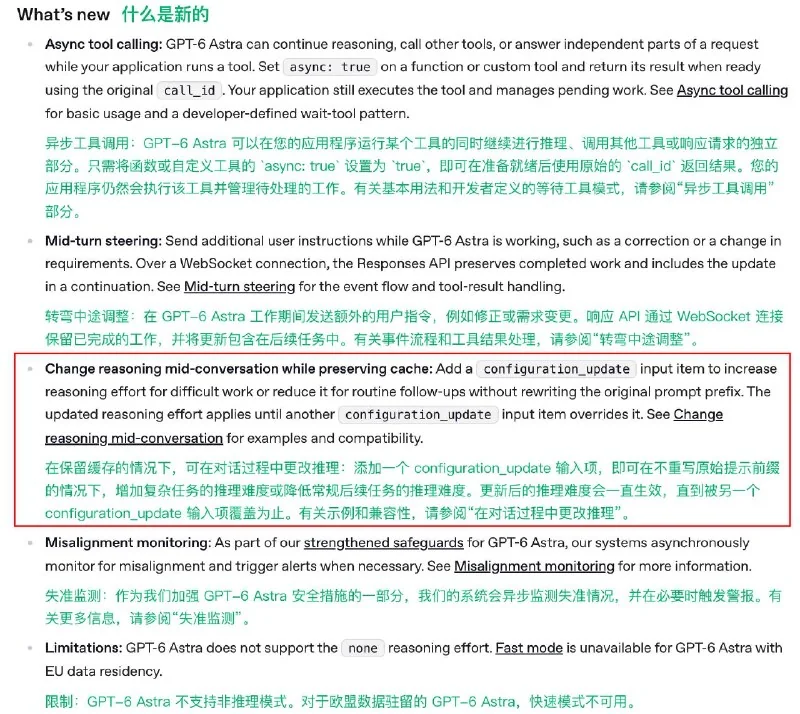
OpenAI has added configuration_update to GPT-6 Astra. In the Responses API, a single long conversation can now raise or lower its reasoning effort at any moment without rewriting the cached prompt prefix. Pump it up to High or xhigh when a problem gets hard, then drop back down to Low once the task turns simple — the earlier long context stays reusable.
Previously, this was a hidden money pit. Reasoning effort is baked into the top of the context as an instruction, so jumping to a new thinking level mid-conversation used to invalidate large chunks of cached tokens. One Codex user measured the effect of shifting gears: cache hit rate plunged from 98.5% to 65% and didn't recover above 97% until the next round rebuilt the cache.
For long-running agents, that makes the feature genuinely practical. Hit a hard problem and you can temporarily crank up reasoning effort; once the work gets simple, drop it back down — without forcing those hundreds of thousands of tokens of earlier context to be re-ingested as normal input.