Ant Group’s Bailing model line has a new healthcare entry: Ling-3.0-flash-Sante. It builds on Ling-3.0-flash with a mixture-of-experts (MoE) architecture — 124 billion total parameters, but only about 5.1 billion get activated for each token.
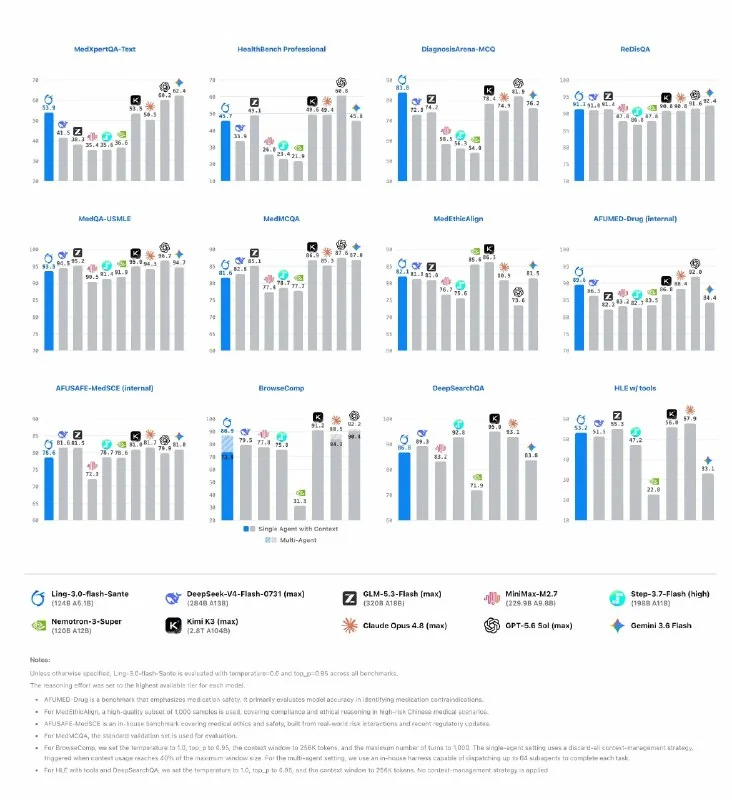
Based on the benchmark results Bailing shared, Sante scored 83.8 on DiagnosisArena-MCQ, ahead of GPT-5.6 Sol’s 81.9, Kimi K3’s 78.4, and Gemini 3.6 Flash’s 76.2. On MedXpertQA-Text, it hit 53.9 — slightly above Kimi K3’s 53.5 but below GPT-5.6 Sol’s 60.2 and Gemini 3.6 Flash’s 62.4.
Multiple-choice exams aren’t the whole story, either. Bailing also tested Sante on BrowseComp, DeepSearchQA, and HLE with tools — benchmarks designed to stress the model’s ability to look up information before answering. Medical ethics and safety get their own numbers, too: 82.1 on MedEthicAlign and 78.6 on the internal AFUSAFE-MedSCE safety test.
Sante is already up on OpenRouter and Vercel, where it can be called for free.
Source: AntLingAGI on X
Follow the Dongcha Beating channel · Join the Dongcha Beating discussion group