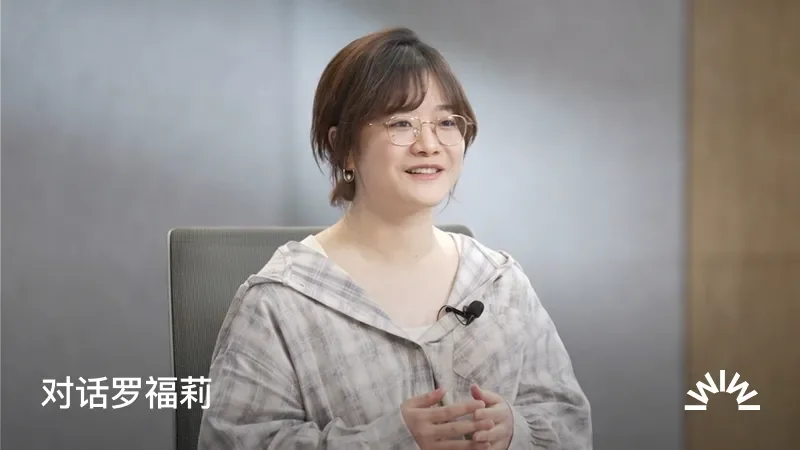
In her first in-depth interview, Xiaomi's large model team lead Luo Fuli dropped some staggering numbers: the MiMo-V2-Pro base model packs 1 trillion parameters, trained on thousands of GPUs. And she says that 1T scale is the absolute floor for matching Claude Opus 4.6-level performance and getting a ticket to the next stage of the Agent race.
Technically, the Pro version pushes the ratio of global attention to sliding window attention to an extreme sparsity of 7:1, keeping long-context inference costs in check while scaling up parameters. It also keeps the MTP (multi-token prediction) architecture, using spare compute to speed up inference.
On the management side, the MiMo team is around 100 people, but only 30 to 40 are directly working on core iterations. There are no job titles, no clear team divisions, and no delivery deadlines. When training loss spikes or other instabilities hit, the team just stops training to debug — even if that means pausing for a week or two and burning millions in compute costs.
Luo Fuli argues that the large model competition has completely shifted from a pre-training-dominated Chat era to a post-training-dominated Agent era. The core race now is "how to scale reinforcement learning on agents."
This paradigm shift has reshuffled compute allocation. In the Chat era, the ratio of compute used for research, pre-training, and post-training was roughly 3:5:1. Today in the Agent era, it's 3:1:1 — pre-training and post-training are now nearly equal, and top teams have already reached a 1:1 split.
The system architecture demands have also changed drastically. Old RL infrastructure was centered on "model inference engines" handling pure text calculations. New infrastructure must be Agent-centric, support heterogeneous cluster scheduling, and tolerate the fuzziness of agents getting interrupted by unpredictable factors in complex workflows.
Luo Fuli says that several Chinese companies, including Kimi and MiMo, already have base models with over 1T parameters, and there's basically no gap between China and the US in pre-training anymore.
She believes Chinese teams have a structural advantage in pre-training, and as long as they react fast enough to the Agent paradigm, the gap to top foreign models like Claude Opus 4.6 is really just two to three months. The next couple of months will be the critical window to test each team's overall research capability, technical agility, and ability to embrace new paradigms.
On the AGI timeline, Luo Fuli estimates we're at 20% progress today, with a jump to 60-70% possible this year, and expects AGI within two years. She credits open-source Agent frameworks like OpenClaw for unlocking collective intelligence, enabling bidirectional iteration between frameworks and models, which is dramatically accelerating progress.