
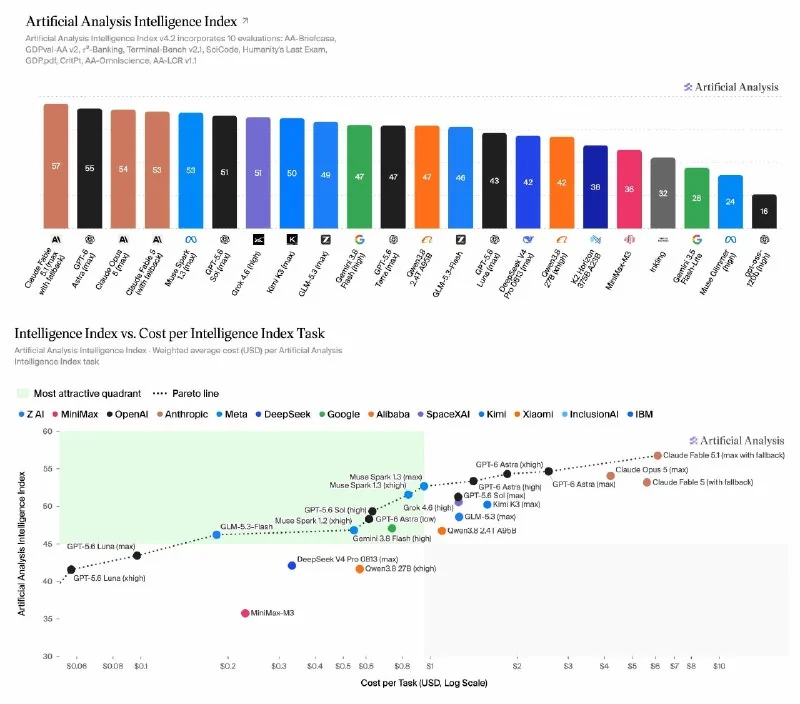
Artificial Analysis updated its Intelligence Index to v4.2, and the headline change is meant to make the leaderboard much harder to game. Private tests now account for 40% of the index weighting, up from 20%, and model makers can't see the full test set in advance. Less room for benchmark-specific fiddling.
The update also adds two new evals. AA-Briefcase simulates a real knowledge-work project that unfolds over weeks, requiring models to juggle a web of related tasks and thousands of documents. GDP.pdf, meanwhile, poses questions based on 100 professional PDFs totaling 4,592 pages, asking models to cross-reference text, tables, charts, and footnotes before they answer.
And out goes GPQA Diamond — at least from the composite index. The graduate-level science QA benchmark has essentially hit a ceiling: GPT-6 Astra tops out at 96.3%, while Gemini 3.8 Flash reaches 95.3%. When everyone's near the top, it stops being useful for separating the best from the rest.
After the reweighting, Claude Fable 5.1 keeps the No. 1 spot, with GPT-6 Astra second at 55 points — four ahead of GPT-5.6 Sol. Artificial Analysis also notes Astra gets there while using fewer output tokens than other frontier models at its level.
https://twitter.com/ArtificialAnlys/status/2096001986110099767