
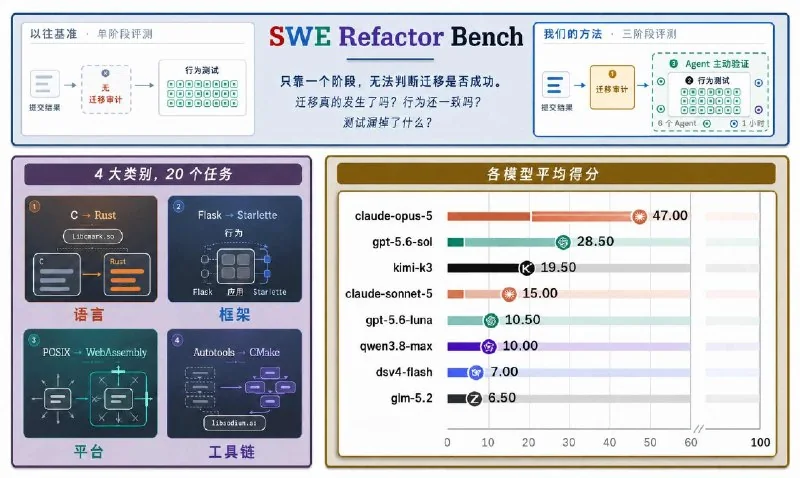
Einsia, an AI agent company, released SWE Refactor Bench, a benchmark that tests whether coding agents can migrate an entire codebase on their own. The 20 tasks are pulled from real projects like SQLite, zlib, libsodium, and GraphHopper. They range from C-to-Rust rewrites and Maven-to-Gradle build migrations to porting SQLite to WASI. Each agent gets six to 30 hours per task.
The evaluation's first gate checks that the old tech stack has actually been replaced, so an agent can't just leave legacy code behind and call it a day. The second gate runs more than 130,000 predefined checks. Finally, six independent coding agents each spend an hour looking for hidden bugs.
Across eight frontier models and 26 configurations, the benchmark ran 520 trials. 340 runs actually completed the migration, and 88 passed all of the prepared tests. But 60 of those were then caught by the final hidden-bug review. In the end, only 28 runs cleared the whole gauntlet — a 5.4% pass rate. Thirteen of the 20 tasks were left unsolved by every model. Claude Opus 5 in its xhigh configuration did best, fully completing five of the 20 tasks.
Today's coding agents can already modify code at scale. But taking an entire system, refactoring it end-to-end, and getting it right with zero errors? That's still a long way off.