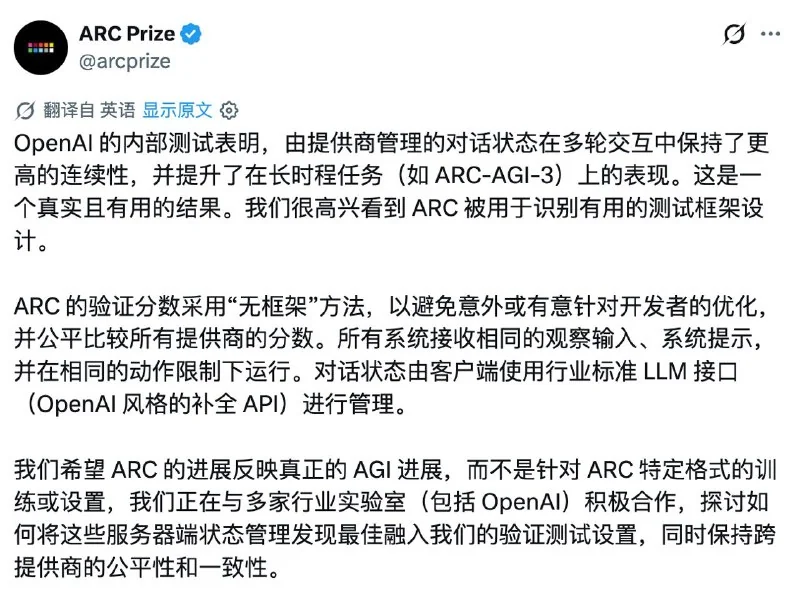
OpenAI claims that the generic ARC-AGI-3 evaluation framework is unfairly dragging down GPT-5.6 Sol's performance — but its rival Opus 5 scored 2.3 times higher under the same conditions. According to OpenAI, the framework fails to preserve GPT-5.6 Sol's previous reasoning steps and even deletes early records when context grows too long. As a result, the model frequently forgets rules it has already discovered, forcing it to re-solve from scratch at every step.
So OpenAI rebuilt the evaluation framework using its own Responses API, retaining historical reasoning and compressing lengthy context. The result? GPT-5.6 Sol's score jumped from 13.3% to 38.3%, while output tokens dropped to roughly one-sixth of the original. But here's the catch: Opus 5, using the exact same original framework, already achieved a score 2.3 times higher than GPT-5.6's revised number...