AI researcher Aran Komatsuzaki did a simple experiment: he translated Rich Sutton's famous essay "The Bitter Lesson" into 9 languages and fed each version into the tokenizers of six major AI models — OpenAI, Gemini, Qwen, DeepSeek, Kimi, and Claude. Using English on OpenAI's tokenizer as a baseline of 1x, he measured how many tokens each language consumed per model. The results are brutal for Anthropic.
Ask Claude the same question in Chinese, and it burns 65% more tokens than English. OpenAI? Just 15% more. Hindi on Claude is even worse — over 3x the baseline. Across all six models, Anthropic's tokenizer is the least efficient for non-English languages.
https://twitter.com/arankomatsuzaki/status/2049177688402022730
Translation changes text length, so comparing across languages isn't perfectly precise. But the real kicker comes when you compare the same Chinese passage across models (same baseline): Kimi uses only 0.81x tokens, Qwen uses 0.85x, and Claude balloons to 1.65x. The text is identical — the difference is pure tokenizer efficiency. Chinese models actually process Chinese more efficiently than English, which means the problem isn't the language itself, but whether the tokenizer was optimized for it.
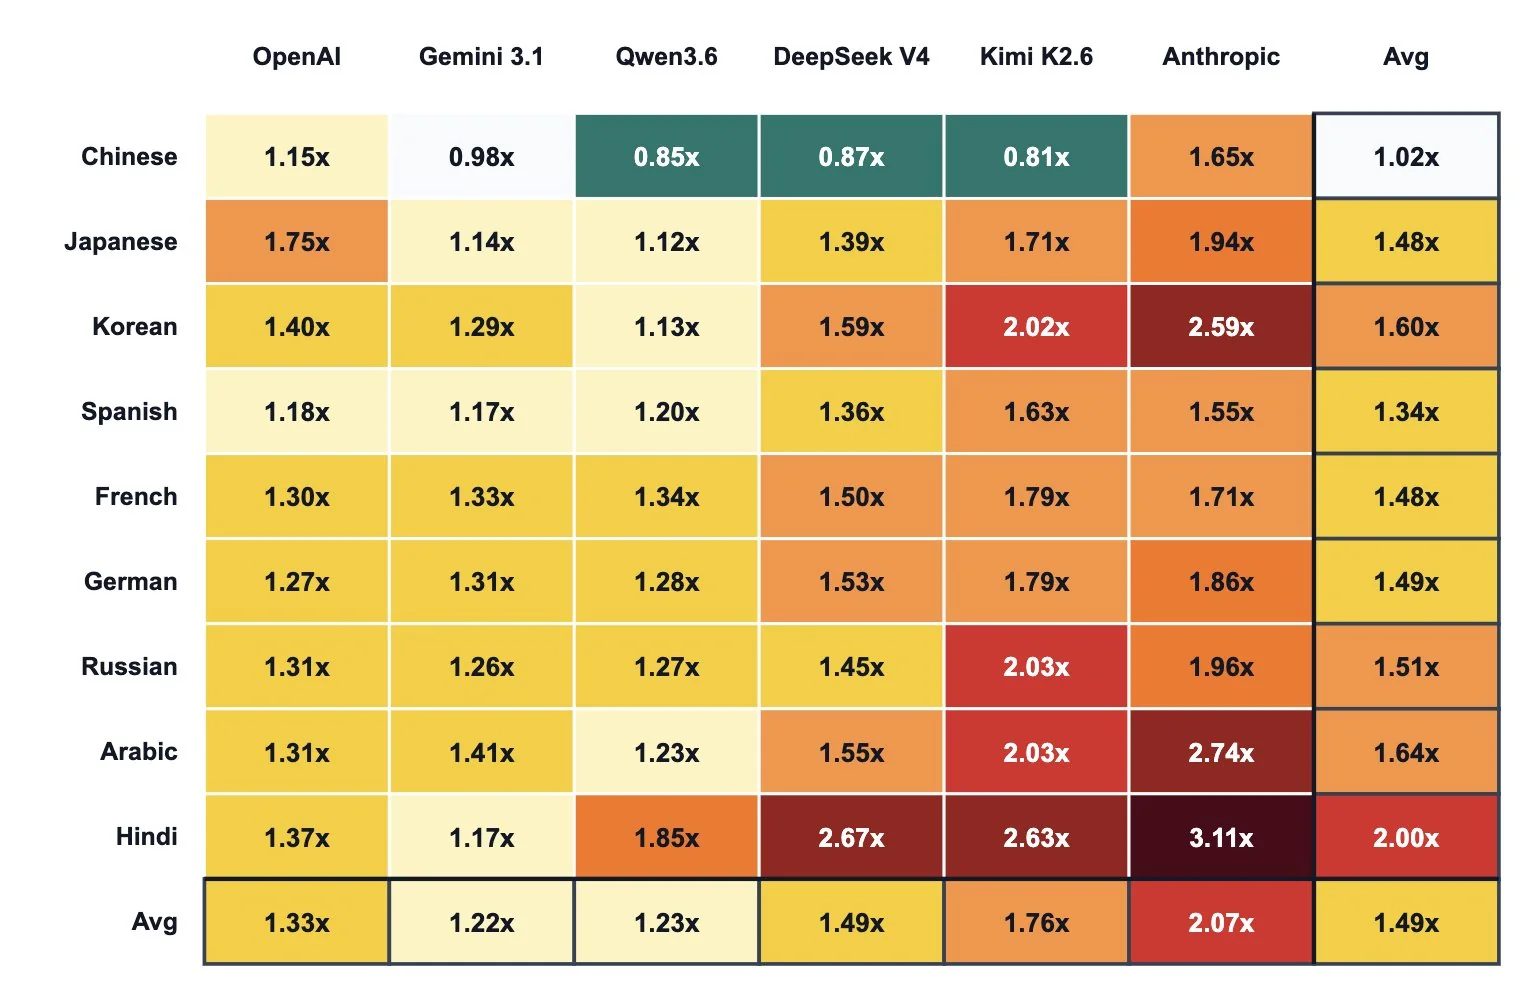
For users, more tokens mean more expensive API calls, longer waiting times before the model responds, and a context window that fills up faster. Tokenizer efficiency boils down to the language mix in training data: lots of English means English words get compressed efficiently; less of a language means it gets chopped into tiny pieces. Aran's conclusion: the bigger the market, the fewer tokens you spend.
This inefficiency isn't lost on developers — just ask DeepSeek, which recently cut its API cache prices to a tenth, betting that cheaper tokens drive adoption. Meanwhile, OpenAI's GPT-5.5 manages to cut token consumption by half for the same tasks, showing what's possible when tokenization is optimized.