
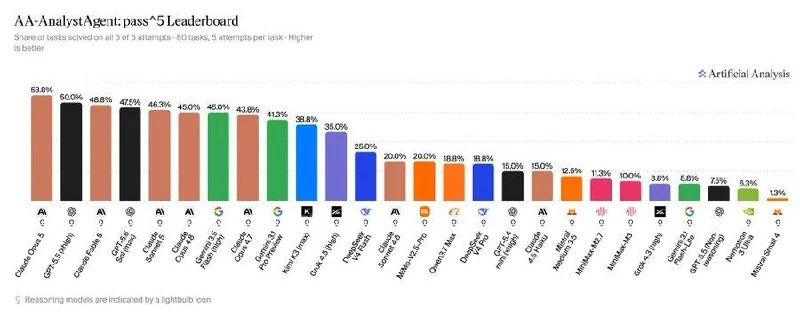
Artificial Analysis has launched a new benchmark for AI analyst skills called AA-AnalystAgent. The test hands models real spreadsheets and documents, then asks them to do data analysis, trend spotting, financial modeling, and other analyst-style work. It's 80 questions total, and each one has to be solved five separate times — a question only counts as passed if the model gets it right all five tries.
The top performer is Claude Opus 5, which still only managed a 54% pass rate after five consecutive tries. GPT-5.5 comes in second at 50%; Claude Fable 5 trails at 49%. Among open-weight models, Kimi K3 does best with 39%.
If you just look at average correctness per attempt, GPT-5.5 actually wins, with 66%. But once you demand five correct answers on the same question, its pass rate drops to 50%. Claude Opus 5's per-attempt score is slightly lower — it's just more consistent, which is why it ends up on top.
The most common failure isn't bad math — it's misreading the problem. Artificial Analysis reviewed 1,567 failed attempts and found 57% involved the model locking onto a wrong interpretation early and then confidently following that path the rest of the way.