DeepSeek V4-Pro tops GPT-5.4 on coding, but lags in knowledge and long context
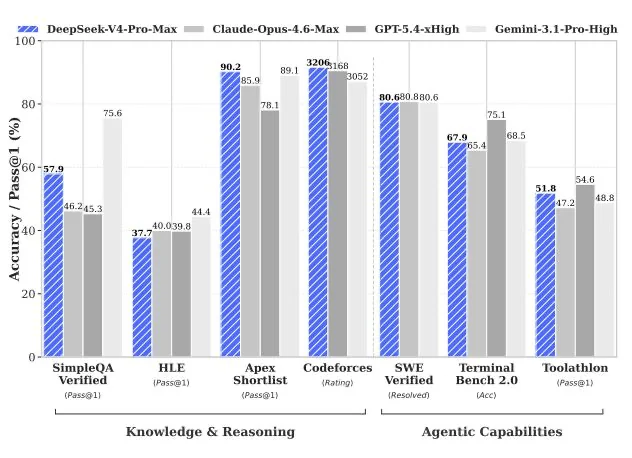
DeepSeek's V4 technical report benchmarks the V4-Pro-Max (max reasoning mode) against closed-source flagships. The comparison set includes Opus 4.6 Max, GPT-5.4 xHigh, Gemini 3.1 Pro High, and open-source models Kimi K2.6 and GLM-5.1, excluding the recently released Opus 4.7 and GPT-5.5.
On coding, V4-Pro-Max scored 3206 on Codeforces, beating GPT-5.4's 3168 and Gemini 3.1 Pro's 3052, setting a new record on that benchmark. It also topped LiveCodeBench with 93.5. On SWE Verified, it got 80.6, just 0.2 points behind Opus 4.6's 80.8.
On long-context tasks, V4-Pro-Max came in second on both 1M benchmarks: CorpusQA 1M scored 62.0, trailing Opus 4.6's 71.7 but ahead of Gemini 3.1 Pro's 53.8; MRCR 1M scored 83.5, with Opus 4.6 leading at 92.9 — nearly 10 points ahead.
On agent tasks, MCPAtlas Public scored 73.6, just below Opus 4.6's 73.8. Terminal-Bench 2.0 scored 67.9, below GPT-5.4's 75.1 and Gemini 3.1 Pro's 68.5.
Knowledge and reasoning remain clear weaknesses: GPQA Diamond 90.1 (Gemini 94.3), SimpleQA-Verified 57.9 (Gemini 75.6), HLE 37.7 (Gemini 44.4). As an open-source model, V4-Pro-Max matches or exceeds closed-source flagships on several coding and long-context benchmarks for the first time, but still trails Gemini 3.1 Pro on knowledge-intensive evaluations.
Note that this comparison does not include the just-released GPT-5.5 and Opus 4.7 — V4's gap against the latest generation of closed models awaits third-party verification.