
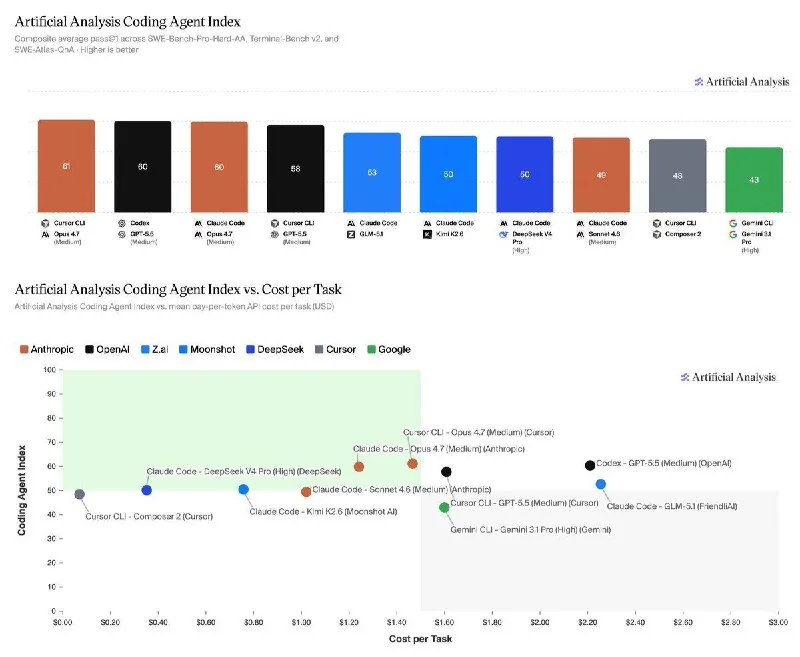
Artificial Analysis has released the first comprehensive benchmark index for coding agents, dubbed the Coding Agent Index. It combines three tests — code generation (SWE-Bench-Pro-Hard-AA), terminal operations (Terminal-Bench v2), and technical Q&A (SWE-Atlas-QnA) — to evaluate AI programmers' real-world engineering performance.
In the inaugural ranking, Cursor CLI paired with the Opus 4.7 model took the top spot with a score of 61, beating OpenAI's Codex (with GPT-5.5) and Anthropic's Claude Code (also with Opus 4.7) by a single point.
When both used the same Opus 4.7 model, Cursor CLI scored 61 versus Claude Code's 60 — but it came at a cost: average task time was longer (7.8 minutes vs. 5.8 minutes), and API calls were pricier ($1.47 vs. $1.24).
The cheapest option was Cursor's built-in Composer 2, at just $0.07 per task. DeepSeek V4 Pro ($0.35) and Kimi K2.6 ($0.76) followed.
But those domestic Chinese models took significantly longer. While Claude Code (with Opus 4.7) finished a single test task in as little as 5.8 minutes, DeepSeek V4 Pro averaged 18 minutes, and Kimi K2.6 dragged on to 41.5 minutes.