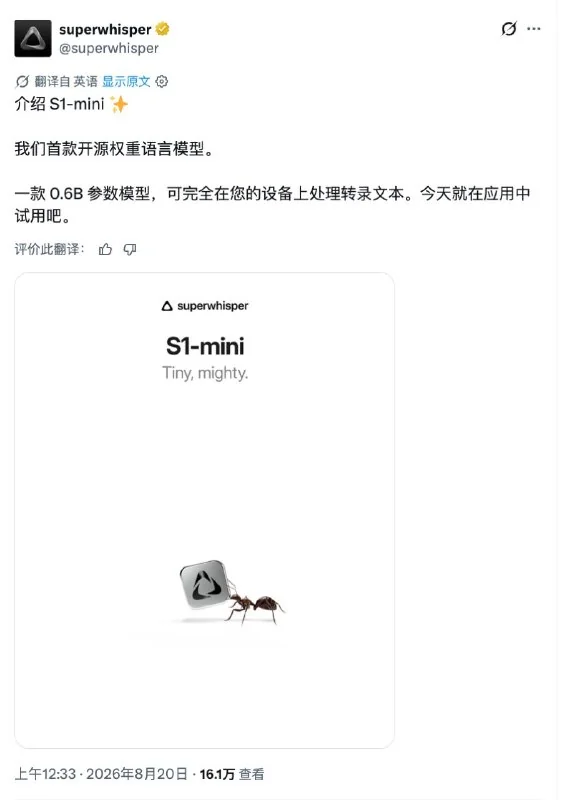
AI voice input tool Superwhisper just released its first open-source model, S1-mini. It's a small model — roughly 600 million parameters — fine-tuned from Qwen3-0.6B, and its job is to clean up raw speech-to-text drafts. The whole thing runs entirely on your local device.
S1-mini doesn't actually listen to audio. Whisper, Parakeet, or another speech recognition model first turns sound into text, then S1-mini takes over. It deletes filler words like "um" and "uh", handles false starts and corrections, adds punctuation and capitalization, and reformats dictated numbers, dates, times, amounts, and email addresses into proper written form.
The model only supports English for now. The official quantized version is about 462MiB and runs on an ordinary laptop CPU. It's also available as GGUF, so you can plug it into llama.cpp, Ollama, or LM Studio. Superwhisper says it measured 94.8% token accuracy on 7,519 English test samples — though it hasn't published any side-by-side comparisons with other text-cleaning models.
S1-mini has actually been running inside the Superwhisper app since June as an experimental feature. At the time, the company said most machines could handle about 200 tokens per second. Now that the weights are public, other voice input, meeting notes, and captioning apps can grab it and deploy it locally.
https://twitter.com/superwhisper/status/2090114882272141760