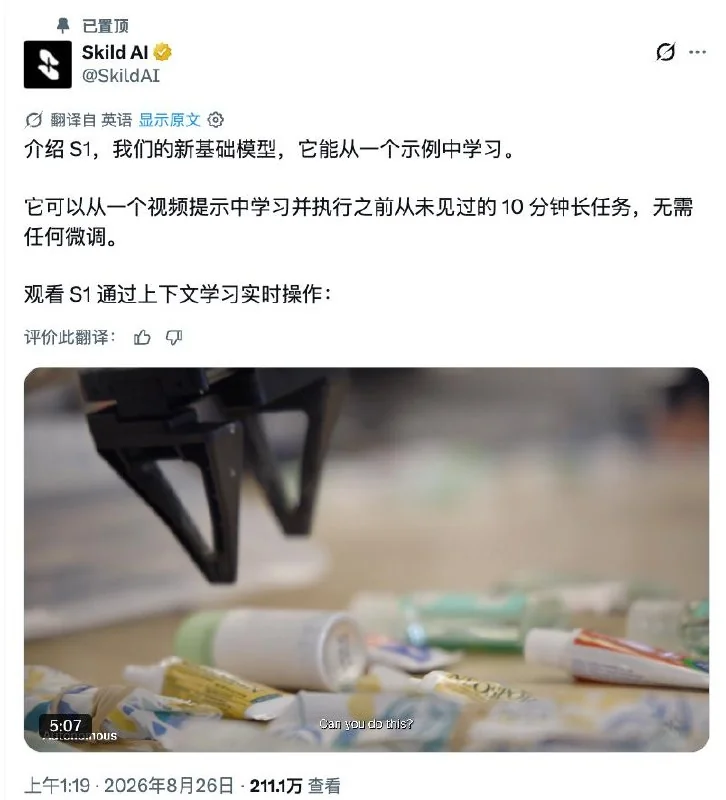
Skild AI, the company building a general-purpose brain for robots, has released its next-generation robot foundation model, S1. The biggest change? You no longer need to fine-tune the model to teach it a new job. Just show it a video of a human performing the task, and it can follow along. In official demos, that includes tasks the system was never trained on — flipping pancakes, making pour-over coffee, repotting a plant — some of which run more than 10 minutes.
S1 essentially treats the demonstration video as a prompt and outputs the robot's actions accordingly. For the plant-repotting test, it took only 11 minutes from the start of recording the human demo to the robot performing the task itself. Even if it's interrupted or makes a mistake mid-task, it keeps adjusting based on the current scene rather than mechanically replaying the video's motions.
In Skild's internal evaluations, both models were pretrained on the same 100,000 hours of data. On unseen new tasks, S1 hit an average single-step success rate of 66%, while a traditional language-instruction VLA (vision-language-action model) only reached 9%. That older approach would need roughly 380 more task demonstrations and fine-tuning to catch up to what S1 achieves after a single video.
S1 is already being deployed to a small number of industrial customers, with wider rollout planned over the next few months.
https://twitter.com/SkildAI/status/2092300842900865389