
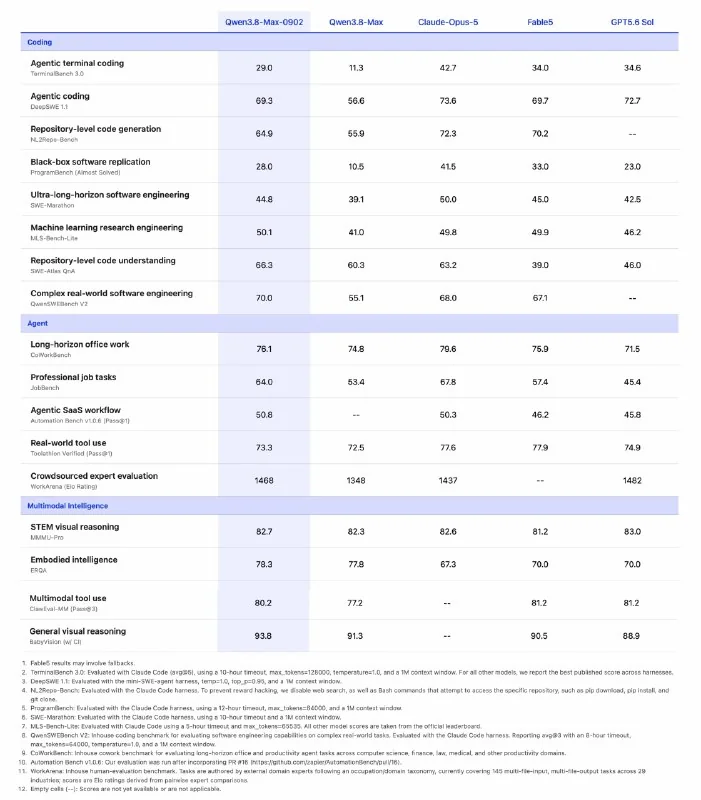
Alibaba has upgraded its Qwen3.8-Max flagship just one month after its initial release, rolling out a new version called Qwen3.8-Max-0902. The parameter count and context window remain unchanged at 2.4 trillion parameters and 1 million tokens, but the team focused this round on continued post-training for coding and collaboration—specifically programming, complex workflows, and long-running agent tasks.
In Alibaba’s own benchmark table, 0902 beats the original model on all eight programming tests. TerminalBench 3.0 jumps from 11.3 to 29.0, DeepSWE 1.1 from 56.6 to 69.3, and QwenSWEbench V2 from 55.1 to 70.0. Even the professional-task benchmark JobBench climbs from 53.4 to 64.0.
Compared with Claude Opus 5, the new Qwen still loses most coding showdowns—but it manages to top Anthropic’s model on MLS-Bench-Lite, SWE-Atlas QnA, and QwenSWEbench V2. On four multimodal benchmarks, the improvement is far quieter, with gains ranging from just 0.4 to 3 points. The message is clear: this update is meant to make agents better at writing code and getting things done. For now, those results are Alibaba’s own self-reported numbers.
Qwen3.8-Max-0902 is now available through the QwenCloud API at the same price as before: $2 per million input tokens and $6 per million output tokens.
https://twitter.com/Alibaba_Qwen/status/2094968708288680276