
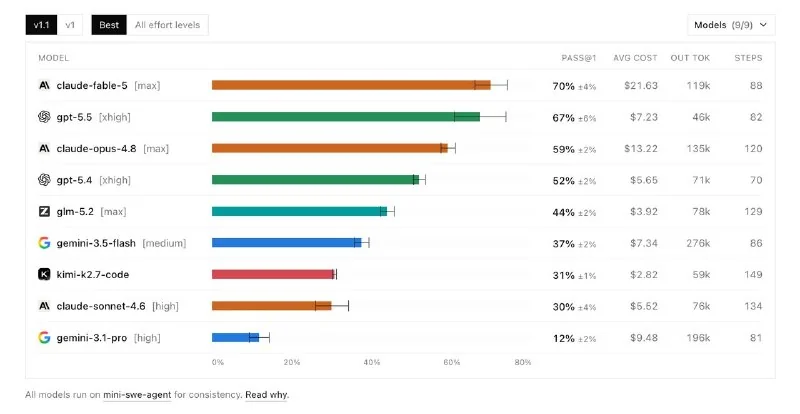
Zhipu AI's open-source model GLM-5.2 has landed on the DeepSWE benchmark for long-context software engineering, and it's already topping the open-source charts. In its maximum-thinking mode, the model achieves a 44% first-attempt success rate on complex development tasks — 13 percentage points higher than the previous open-source leader, Kimi K2.7 Code.
Each task costs an average of $3.92, slightly more than Kimi K2.7 Code's $2.82, but that extra compute buys results that surpass several major closed-source models under specific thinking configurations. For comparison: Claude Sonnet 4.6 [high] hit 30%, Gemini 3.5 Flash [medium] managed 37%, and Claude Opus 4.8 [low] scored 41%.
The DeepSWE benchmark, designed by evaluation firm Datacurve, specifically tests AI agents' ability to handle long, multi-step coding tasks. It includes 113 real-world programming problems spanning five languages. Unlike traditional tests that only require single-file edits, DeepSWE demands coordinated changes across multiple files, with an average of over 600 lines of code modified per task. The evaluation runs in isolated containers with strict CPU and memory limits.