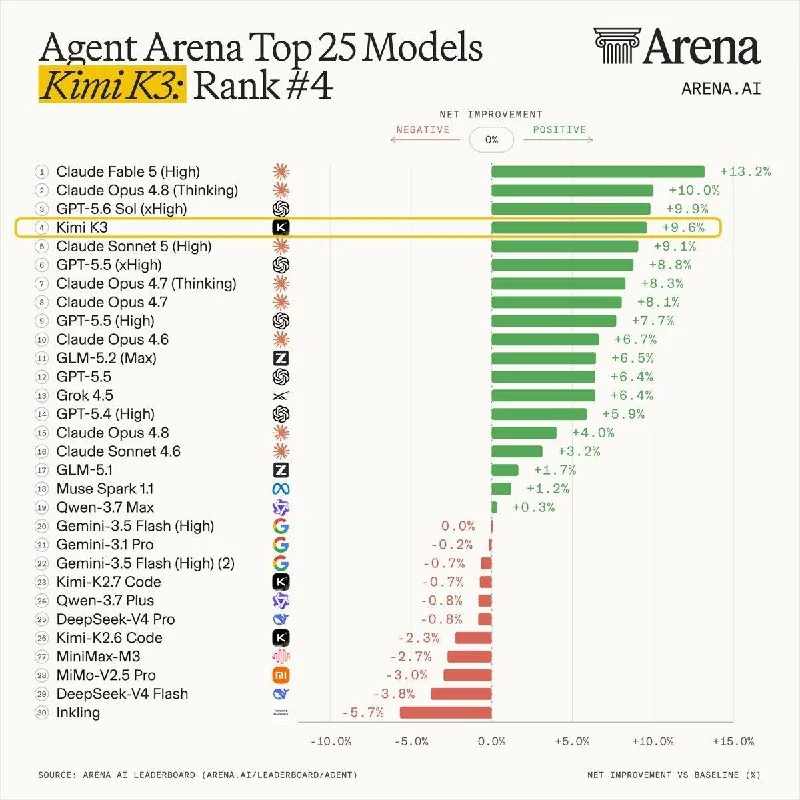
Arena's Agent leaderboard measures real user tasks and tool calls. Kimi K3 scored a net improvement of 9.62%, landing at #4 overall — behind Claude Fable 5, Claude Opus 4.8 Thinking, and GPT-5.6 Sol.
The benchmark blends all models into a virtual average baseline, then estimates how much swapping in K3 would improve results across five metrics. The overall score is the average of those net gains.
K3 has logged 8,344 test sessions so far. Its biggest win: a 14.42% net improvement in the user-confirmed success metric, ranking #1. It also scored a 20.62% net gain in praise-over-complaints, good for #3. But it's weaker at mid-task corrections (#14) and recovering from Bash errors (#17).
In short, K3 is good at producing results users actually like — but fixing mistakes mid-stream and handling command failures still need work.
https://twitter.com/arena/status/2079253211077300736