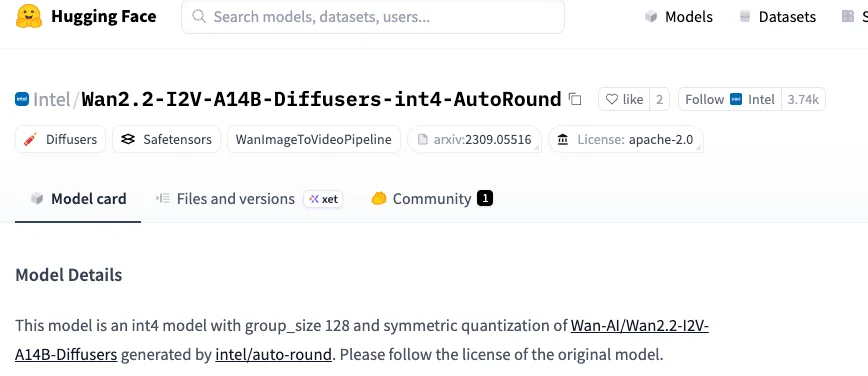
Intel's chief AI engineer Haihao Shen announced the company has uploaded three INT4-quantized versions of Alibaba's Wan 2.2 video model to Hugging Face. The models—T2V-A14B (text-to-video), I2V-A14B (image-to-video), and TI2V-5B (text-and-image-to-video)—were all compressed to W4A16 using AutoRound, a quantization tool Shen himself helped author.
INT4 compression shrinks each weight from 2 bytes in BF16 format down to 0.5 bytes, reducing the overall weight size to roughly a quarter of the original. That's a significant space saver for models that were already pushing hardware limits.
https://twitter.com/HaihaoShen/status/2046353772625137879
The two A14B models originally used a mixture-of-experts (MoE) architecture, with 27 billion total parameters and 14 billion activated per step. Official documentation claimed running them at 720p required at least 80GB of VRAM on a single GPU. The TI2V-5B, however, is a dense model that could already run 720p at 24 frames per second on an RTX 4090 in its original form.
Intel hasn't released any benchmarks showing the quantized versions' actual VRAM usage or image quality compared to the originals—that data will have to wait for third-party testing. And if you want to run these models, you can't just use the standard vLLM inference pipeline. The README points to Intel's own vllm-omni branch (feats/ar-w4a16-wan22), which you'll need to install to get the service up and running.