
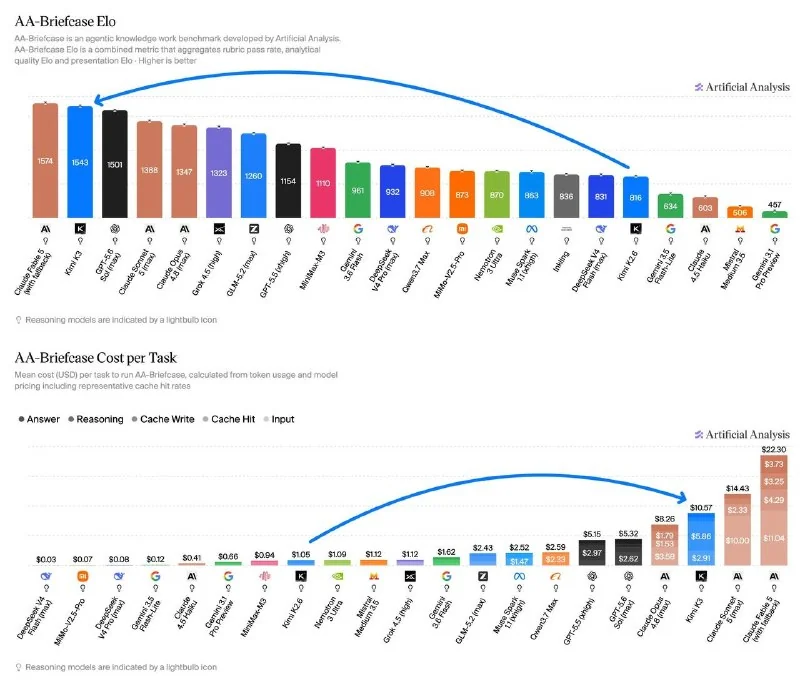
AA-Briefcase, a new benchmark designed specifically for long-cycle knowledge work performed by AI agents, has been released by testing organization Artificial Analysis. It covers four real-world business scenarios — data science, product management, banking operations, and heavy industry strategy — developed by industry experts from Google, McKinsey, and Boston Consulting Group. The benchmark includes 91 tasks simulating complex commercial workflows. Models are evaluated via objective questions, analysis quality, and presentation formatting through head-to-head comparisons and standard benchmarks. According to the results, Anthropic's Claude Fable 5 took first place, while GLM-5.2 cracked the top three.