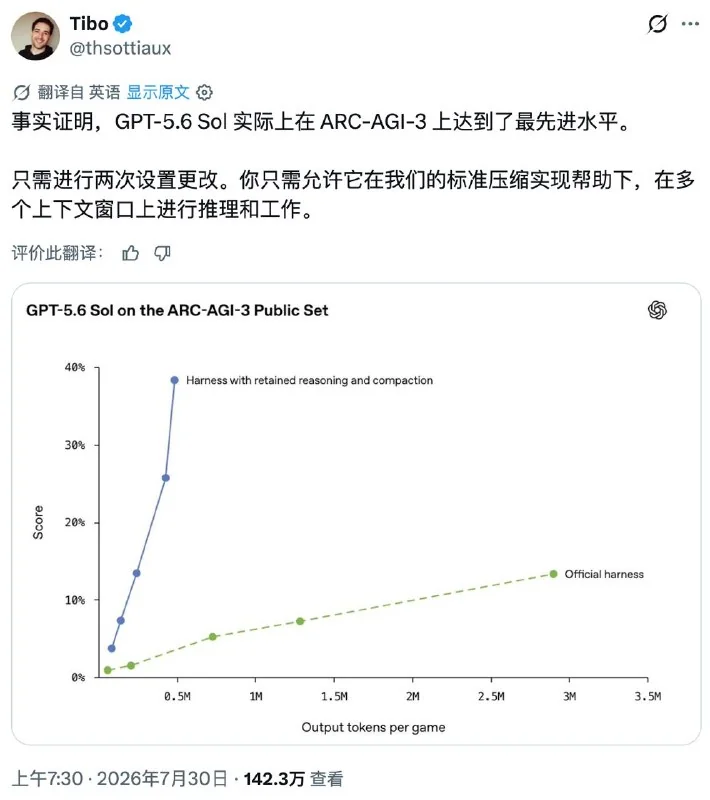
The ARC-AGI-3 paper introduces two separate leaderboards. The official leaderboard bans external harnesses (agent frameworks), requiring all models to use the same minimal prompt with no tools — it's a test of raw, scaffold-free intelligence. The community leaderboard, on the other hand, allows harnesses, scores are self-reported, and the ARC Prize defaults to no verification. The paper explicitly warns that "scores on the community leaderboard should not be interpreted as evidence of AGI progress."
On the official leaderboard, frontier models all score below 1%: Gemini 3.1 Pro Preview achieves 0.37%, GPT...