Mira Murati is coming for her old boss. The former OpenAI CTO's new startup, Thinking Machines Lab, just dropped a research preview of what it calls an "interactive model" — and it's designed to do everything GPT-Realtime does, only faster.
The system ditches the hacky approach of stitching together separate speech and text modules. Instead, it natively processes real-time audio and video. The model operates in 200-millisecond "micro-rounds," constantly ingesting information as it listens, watches, and speaks — and users can interrupt it at any time.
The first model shown, TML-Interaction-Small, uses a 276-billion-parameter MoE architecture, activating just 12 billion per query. To fix a common flaw in large language models — that they stop sensing the world while generating a response — the team split the system into front-end and back-end. The front-end model keeps the conversation going without interruption, while the back-end handles heavy lifting like reasoning, web searches, or UI generation, streaming results back seamlessly.
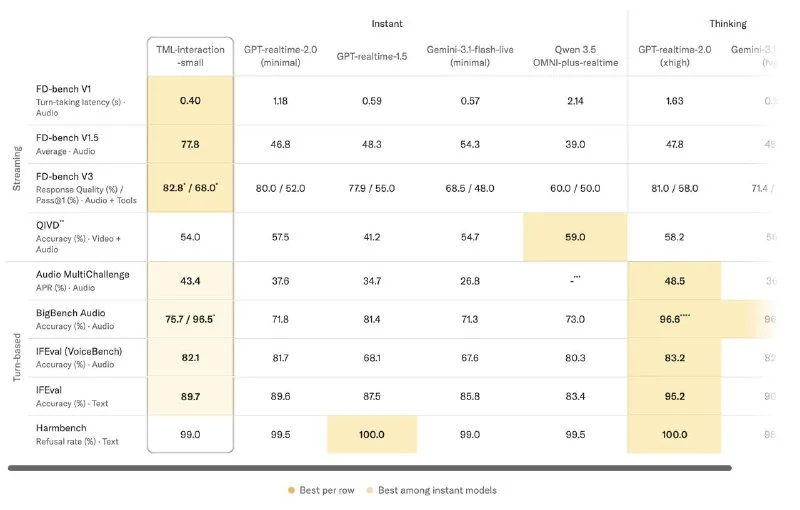
The architecture pays off on speed. According to Thinking Machines, the voice turn-around latency is just 0.40 seconds, and it scored 77.8 on the FD-bench V1.5 benchmark — both metrics beating OpenAI's GPT-realtime-2.0 and Google's Gemini 3.1 Flash Live. But continuous audio-video processing chews through context fast, and low latency depends heavily on network conditions. Thinking Machines plans to open a limited preview in the next few months.