
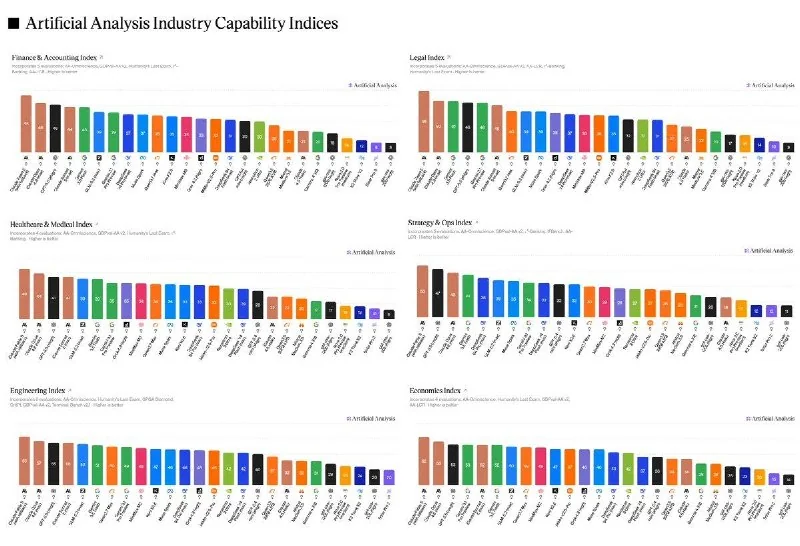
Forget those generic academic benchmarks that never seem to predict real-world performance. Artificial Analysis, the outfit already running agent and coding skill indices, just dropped six new industry-specific indexes covering finance, law, healthcare, operations, engineering, and economics.
https://twitter.com/ArtificialAnlys/status/2074299714699469221
The secret sauce? They're using O*NET's job activity taxonomy to weight tasks based on how frequently they actually pop up in the real workplace. Then they mix in the usual model capability tests — HLE reasoning, LCR long-context handling, GDPval agent work — with a new domain knowledge base called AA-Omniscience.
In the first run, closed-source Claude Fable 5 swept all eight indexes. But the real story might be open-source GLM-5.2, which grabbed first place in five out of six industry indexes and scored 53 on engineering — just two points shy of Claude Sonnet 5's 55.
The cost differences are staggering. On operations, Claude Fable 5 costs $3.48 per task — over a hundred times more than open-source DeepSeek V4 Pro's $0.03. And on the legal index, Gemini 3.1 Pro Preview runs nearly 7x faster than Claude Fable 5 while scoring only 11 points lower.
Balancing performance with cost is quickly becoming the new standard for choosing AI in specific verticals.