The benchmarking firm Artificial Analysis has overhauled its AI Intelligence Index. Instead of just multiple-choice questions, the new test challenges models to autonomously plan, use tools, and solve complex tasks. Gone are the simple instruction-following exercises; in come high-stakes scenarios like simulating a real bank customer service conversation. For the first time, the cost and time to complete a task are core metrics.
https://twitter.com/ArtificialAnlys/status/2066700136018071841
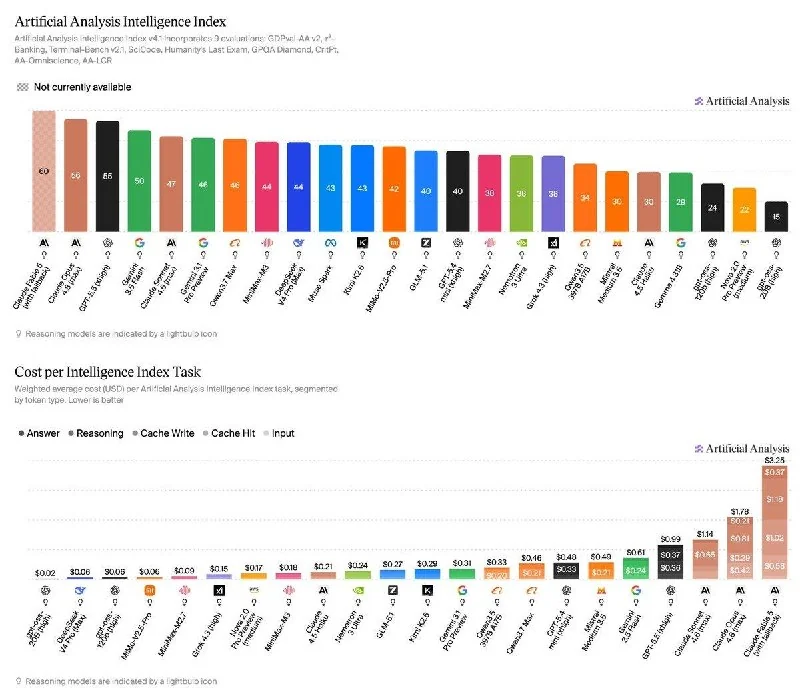
In the latest results, the now-discontinued Claude Fable 5 – taken offline due to US government restrictions – scored a top 60. Among currently available models, the pricey Claude Opus 4.8 leads with 56 points, narrowly beating GPT-5.5 at 55. Chinese domestic models also shine: open-source DeepSeek V4 Pro and MiniMax M3 both score 44, followed by Kimi K2.6 at 43.
The cost gap is staggering. Running one task on Claude Opus 4.8 costs $1.78, while DeepSeek V4 Pro does the same for only $0.04 — that’s 44 times cheaper. Wait times vary too: xAI’s Grok 4.3 is fastest at 1.5 minutes, while Claude Sonnet 4.6 drags at 13.5 minutes.
The most heavily weighted single test in the revamp is GDPval-AA, now in its second version and accounting for 20% of the score. It sets human performance at 1,000 points, rotates several frontier models as judges, and allows up to 250 conversation turns per session.