
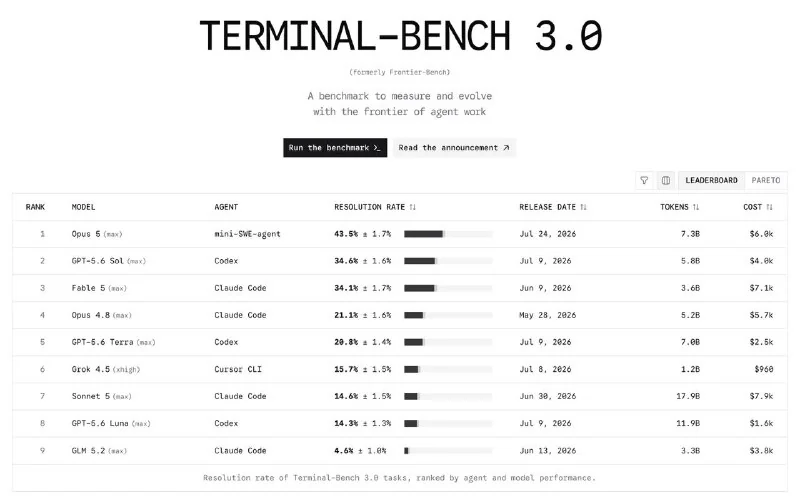
Terminal-Bench 3.0 just crowned a new king. The benchmark drops AI agents into a real terminal environment to complete tasks, then directly checks whether the results are correct.
Current top three:
- Claude Opus 5 Max + mini-SWE-agent: 43.5%
- GPT-5.6 Sol Max + Codex: 34.6%
- Claude Fable 5 + Claude Code: 34.1%
Terminal-Bench 3.0 launched on July 23 with the explicit goal of making things hard again. Frontier model scores had bunched up on the old version; the new one is meant to spread the pack back out. The first release includes 74 tasks across 7 domains, plus more complex environments with GPUs and multi-container networking. And it's not just writing code: tasks can require submitting model weights, formal proofs, spreadsheets, and CAD files.
But you shouldn't read this as Opus 5 itself being nearly 9 points stronger than Sol. Terminal-Bench lets models pair with different agents, and the top three used mini-SWE-agent, Codex, and Claude Code respectively. The agent determines how the model calls tools, executes commands, and handles context, so the leaderboard is really measuring the entire model-plus-agent system.