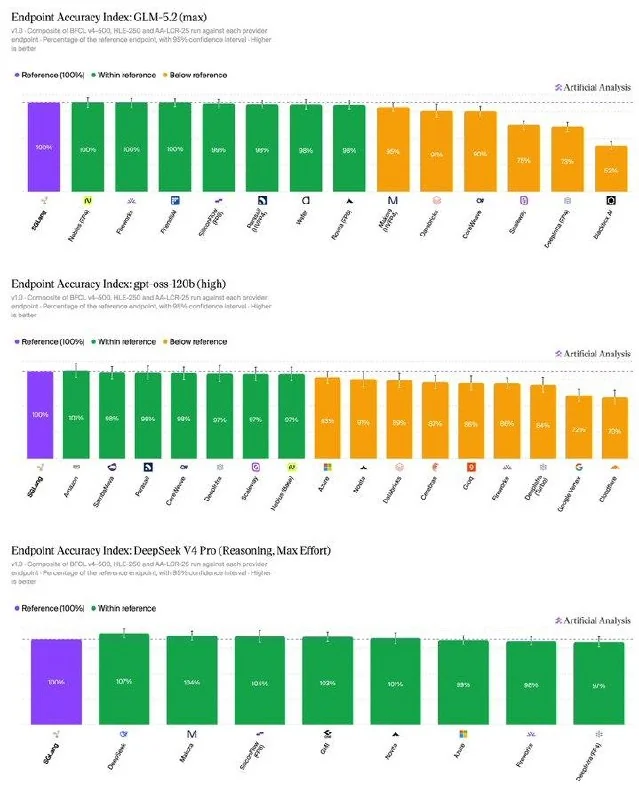
Model evaluation outfit Artificial Analysis has launched an API accuracy leaderboard that tests how much of an open-source model's capability survives when served by different providers. The first batch covers GLM-5.2, gpt-oss-120b, and DeepSeek V4 Pro across 44 API endpoints.
Providers include AWS, Microsoft Azure, Google Vertex, Cloudflare, as well as AI inference platforms like Fireworks, DeepInfra, CoreWeave, and SiliconFlow. Artificial Analysis deploys the official models itself, sets that score at 100%, and then runs the same questions against each provider's API.
Results: the worst GLM-5.2 endpoint scored only 52% — almost half. gpt-oss-120b came in between 70% and 101%. DeepSeek V4 Pro was the steadiest, with all nine providers landing between 97% and 107%, and the official API taking the top score.
The differences mostly come down to quantization, output length, reasoning configuration, and tool-calling handling. The same model name can mean wildly different real-world performance, so choosing an API isn't just about price and speed.
https://twitter.com/ArtificialAnlys/status/2084702191466725669