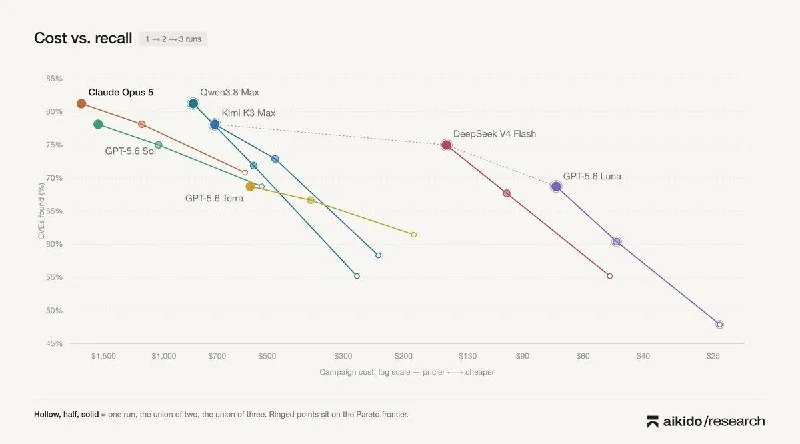
Security firm Aikido recently used a code-auditing agent to put seven AI models to the test. The lineup included Qwen3.8-Max, Claude Opus 5, Kimi K3 Max, DeepSeek V4 Flash, and GPT-5.6's Sol, Luna, and Terra variants. The challenge: 32 recently disclosed vulnerabilities, with each model running the task three times.
Qwen3.8-Max spotted 26 of the 32 vulnerabilities across its three runs, a recall rate of 81.3% — good enough to tie Opus 5 for first. Its F1 score, which balances false positives and false negatives, was 83.2%, slightly below Opus 5, Kimi K3 Max, and GPT-5.6 Sol.
The catch is consistency. Qwen only managed to find 10 of its 26 vulnerabilities in every single round; Opus 5 and Sol each nailed 19 across all three. Qwen's total cost, however, was about $821 — half of what Opus 5 and Sol cost, but still five times pricier than DeepSeek V4 Flash.
https://twitter.com/pilvar222/status/2084667774559785261