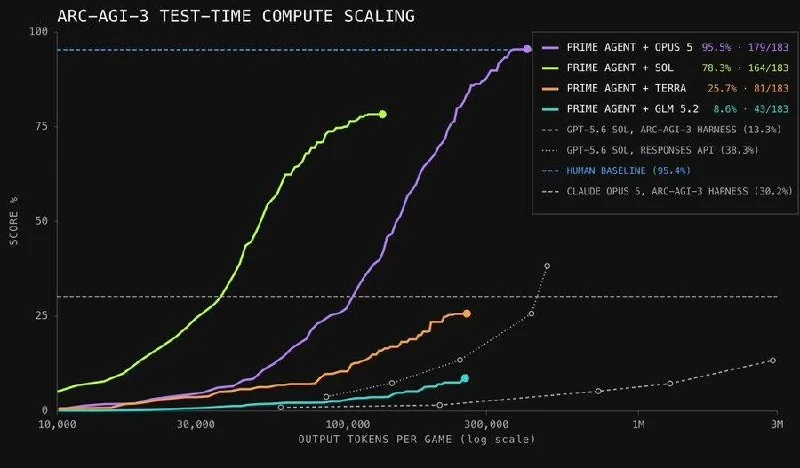
ARC-AGI-3’s new paper splits the benchmark into two leaderboards, and the scoring gap between them is impossible to miss.
The official leaderboard bans external harnesses — agent frameworks — so every model has to make do with the same minimal prompt and no tools. It’s a raw test of native intelligence, with no scaffolding to lean on. There, frontier models all score below 1%: Gemini 3.1 Pro Preview sits at 0.37%, GPT…
The community leaderboard is a completely different animal. Harnesses are allowed, and scores are self-reported. ARC Prize doesn’t verify them by default — and the paper is blunt: “scores on the community leaderboard should not be interpreted as evidence of AGI progress.” That warning exists for good reason. Give the same models an agent framework, and the numbers tell a much flashier story: 36% on day one.