 AI Apple quietly registers genai.apple.com subdomain ahead of WWDC26
Top Stories
Pinned News
AI Apple quietly registers genai.apple.com subdomain ahead of WWDC26 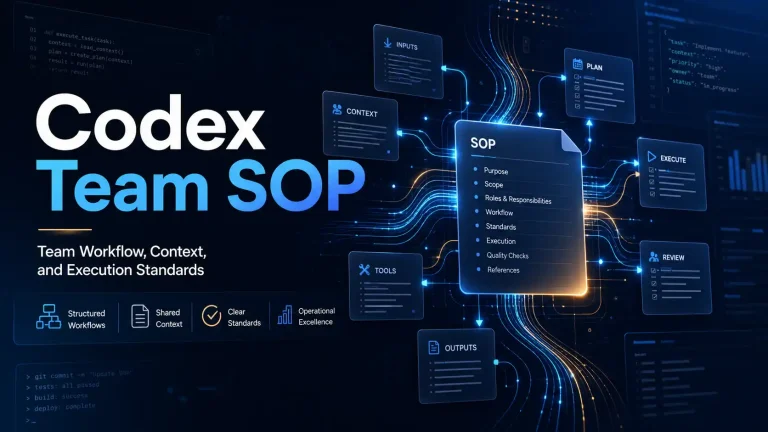 Developer Context Is a Budget — Not a Trash Can
 OpenAI Codex: More Than a Coding Assistant, It's a Work Automation System
 Anthropic Why Claude Code Is Ditching Markdown for HTML
 Anthropic Elon Musk shuts down xAI, hands its 220,000 GPUs to Claude
 AI Musk's lawyers may have just blown open the xAI-OpenAI probe
 OpenAI The decade of OpenAI: ambition, conflict, and betrayal
News,Images,Videos
Most Recent
DeepSeek's Claude Code rival Harness is coming alongside V4
CodeRabbit has raised $143 million at a $1.5 billion valuation, with Atomico and Smash Capital leading. The AI code review startup now checks over 2 million code changes weekly for 17,000 customers.
OpenAI resets everyone's Codex credits as active users top 15 million
CodeRabbit has raised $143 million at a $1.5 billion valuation, with Atomico and Smash Capital leading. The AI code review startup now checks over 2 million code changes weekly for 17,000 customers.
Ex-Huawei chief expert's memory startup raises hundreds of millions after 5 months
Terminal-Bench 3.0 has a new leader: Claude Opus 5 Max + mini-SWE-agent tops the board at 43.5%, beating GPT-5.6 Sol Max with Codex. But the benchmark measures the model and agent together, not the model alone.
Tencent's AI Spending Spree Drains Q2 Free Cash Flow to Negative 13.8B Yuan
Terminal-Bench 3.0 has a new leader: Claude Opus 5 Max + mini-SWE-agent tops the board at 43.5%, beating GPT-5.6 Sol Max with Codex. But the benchmark measures the model and agent together, not the model alone.
Tencent Maps a Five-Level Path for AI Self-Evolution
Terminal-Bench 3.0 has a new leader: Claude Opus 5 Max + mini-SWE-agent tops the board at 43.5%, beating GPT-5.6 Sol Max with Codex. But the benchmark measures the model and agent together, not the model alone.
Mistral Just Welcomed China's GLM-5.2 Into Its 'Sovereign AI' Club
Terminal-Bench 3.0 has a new leader: Claude Opus 5 Max + mini-SWE-agent tops the board at 43.5%, beating GPT-5.6 Sol Max with Codex. But the benchmark measures the model and agent together, not the model alone.
Claude's distillation defenses are failing: small models can extract hidden chain-of-thought
Terminal-Bench 3.0 has a new leader: Claude Opus 5 Max + mini-SWE-agent tops the board at 43.5%, beating GPT-5.6 Sol Max with Codex. But the benchmark measures the model and agent together, not the model alone.
Jeff Dean's final 48 hours at Google: 1,500 goodbyes in a 300-person cafe
Terminal-Bench 3.0 has a new leader: Claude Opus 5 Max + mini-SWE-agent tops the board at 43.5%, beating GPT-5.6 Sol Max with Codex. But the benchmark measures the model and agent together, not the model alone.
Grok Bot is SpaceXAI's tireless AI coworker that works while you sleep
Terminal-Bench 3.0 has a new leader: Claude Opus 5 Max + mini-SWE-agent tops the board at 43.5%, beating GPT-5.6 Sol Max with Codex. But the benchmark measures the model and agent together, not the model alone.
Tencent invests $20M in ex-Alibaba Qwen lead's new AI lab, valued at $2B
Terminal-Bench 3.0 has a new leader: Claude Opus 5 Max + mini-SWE-agent tops the board at 43.5%, beating GPT-5.6 Sol Max with Codex. But the benchmark measures the model and agent together, not the model alone.