Tencent's Hunyuan team, in collaboration with multiple universities, has released LHTB (Long-Horizon Task Benchmark), a test designed to see if AI agents can persistently complete complex tasks in a terminal environment.
The benchmark includes 46 tasks covering software engineering, experiment replication, scientific computing, and multimodal analysis. Each task can run up to 90 minutes and typically requires hundreds of continuous operations.
LHTB doesn't just look at final success or failure. If an agent completes part of a task, it gets partial credit based on actual progress. A hidden validator checks files, test results, and program output — the agent claiming it's done doesn't count.
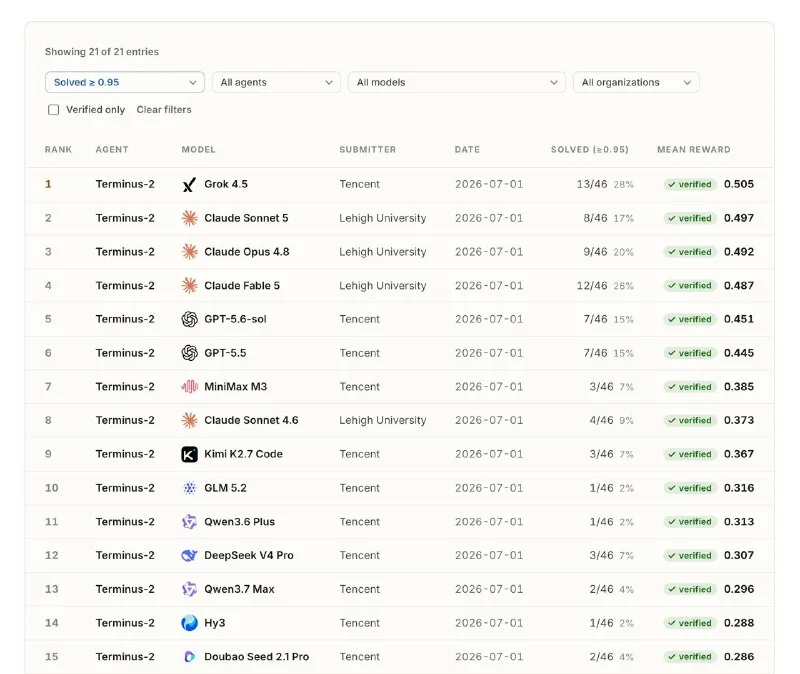
An initial version of the paper tested 15 models. GPT-5.5 completed 7 tasks, ranking first. Each model consumed an average of about 9.9 million tokens per task and took roughly 85 minutes.
The current public results have expanded to 20 models. Grok 4.5 tops the leaderboard with an average score of 0.505, completing 13 tasks. Of the 46 tasks, 29 still have no model meeting the completion criteria.
Most agents can complete some steps but often run out of the 90-minute window or stop early before the task is truly finished, failing to see complex tasks through to the end.