
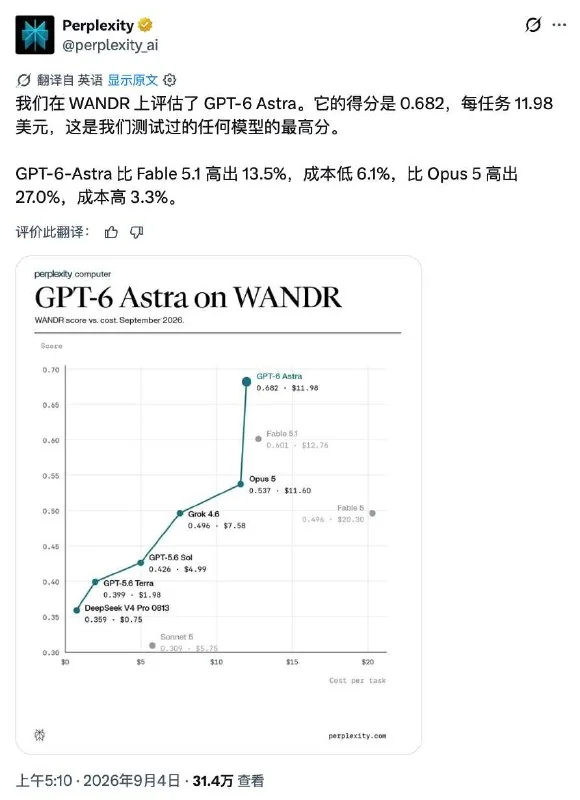
Perplexity just pitted GPT-6 Astra against its own research-agent benchmark, WANDR, and the model walked away with the highest score the company has ever recorded: 0.682, at an average cost of $11.98 per task.
Compared to Claude Fable 5.1, that's a 13.5% higher score at a 6.1% lower cost. Against Opus 5, Astra scores 27% higher while costing just 3.3% more.
WANDR is built for research tasks that are both broad and deep. It runs 500 real-world research scenarios that require an agent to do more than surface a few answers: the agent has to track down every qualifying target, verify each one, and back each result with a citable source. Think competitor research, due diligence, literature searches, market analysis, and talent scouting.
Fable 5.1 previously held the top spot with 0.601 at $12.76 per task, followed by Opus 5 at 0.537 and $11.60. Astra didn't just nudge the bar upward — it pushed it a solid chunk higher, and it didn't brute-force its way there with a dramatically bigger budget.
https://twitter.com/perplexity_ai/status/2095620419906830788