
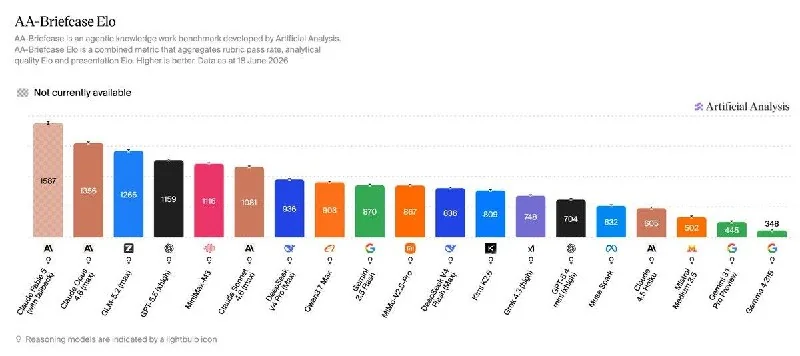
Benchmarking outfit Artificial Analysis has launched AA-Briefcase, the first long-duration knowledge work benchmark designed specifically for AI agents. It covers data science, product management, banking operations, and heavy industry strategy — four scenarios developed by industry experts from Google, McKinsey, and BCG. With 91 tasks, it's meant to simulate real-world, complex business workflows.
The benchmark evaluates performance through objective questions, analysis quality, and formatting presentation, using head-to-head comparisons and absolute scoring. Anthropic's Claude Fable 5 took the top AA-Briefcase Elo rating, followed by Claude Opus 4.8 (max) and GLM-5.2 (max) in second and third place. But even the winner stumbled: Claude Fable 5 managed a perfect score on only 3% of tasks, and for 31 of the 91 tasks, no model could even crack 50%.
On the open-source side, Zhipu AI's GLM-5.2 (max) impressed — its overall score came within 90 points of Claude Opus 4.8 (max), yet its runtime cost was less than 25% of its rival. Costs vary wildly across models: DeepSeek V4 Flash goes for just $0.04 per task, while the priciest contender, Claude Fable 5, costs over $31 per task. The analysis also found that visual inspection skills are critical for delivering well-formatted outputs — the two top scorers in formatting, Claude Fable 5 and Claude Opus 4.8 (max), called image viewing tools an average of 21 and 12 times per task, respectively.