ByteDance is reportedly in early discussions about training a large language model with more than 5 trillion parameters — a scale that would nearly double the size of Moonshot AI's Kimi K3. The company is betting that raw scale will help it close the gap with leading rivals at home and abroad.
If the plan goes through, it would surpass Alibaba's Qwen3.8-Max at 2.4 trillion parameters and Moonshot AI's Kimi K3 at 2.8 trillion, making it the largest known model in China by parameter count. But the project is still in its early stages; whether it actually gets trained and released remains undecided.
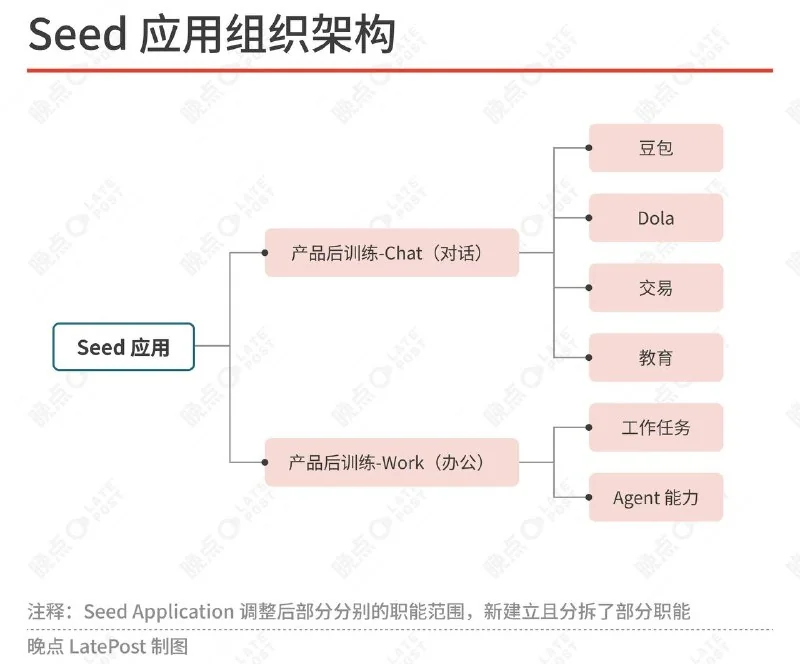
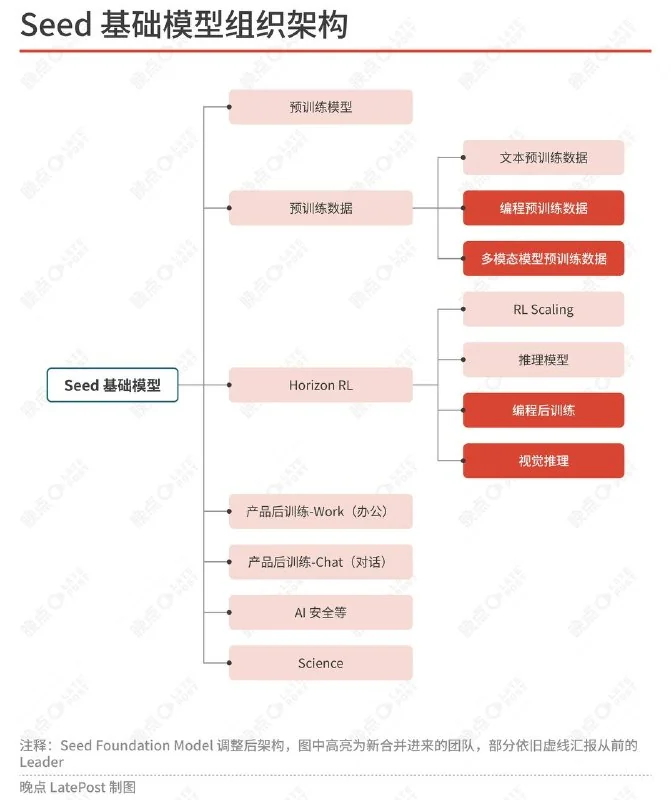
The new model is expected to be led by Xiang Liang, head of Seed Foundation, in collaboration with Shen Ke, who leads LLM pretraining data efforts. Seed is currently reshuffling team responsibilities and allocating resources for the project. …