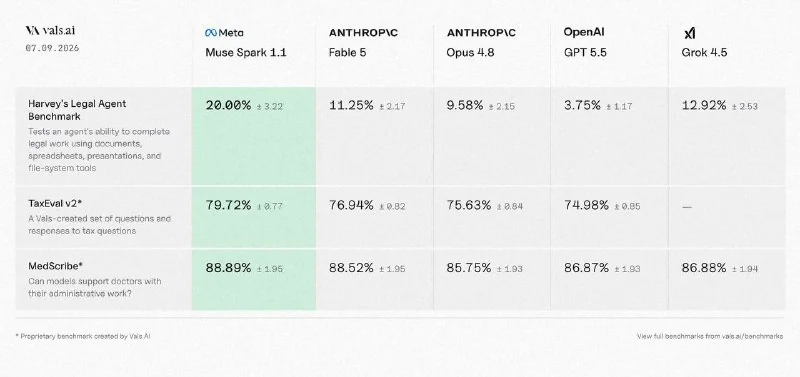
AI evaluation firm Vals AI has released results for Muse Spark 1.1, Meta's latest model. It took first place across three benchmarks: medical documentation (88.89%), tax Q&A (79.72%), and legal agent tasks (20.00%).
On the TaxEval v2 benchmark, it outperformed Fable 5, Opus 4.8, and GPT-5.5. The test includes over 1,200 unpublished questions and checks both answers and reasoning. The top models are tightly clustered — the top ten are separated by less than 3 percentage points.
In the legal agent evaluation, Muse Spark 1.1 scored 20.00%, beating Grok 4.5 (12.92%) and Fable 5 (11.25%). The benchmark required models to use document, spreadsheet, and file tools to complete realistic legal tasks.
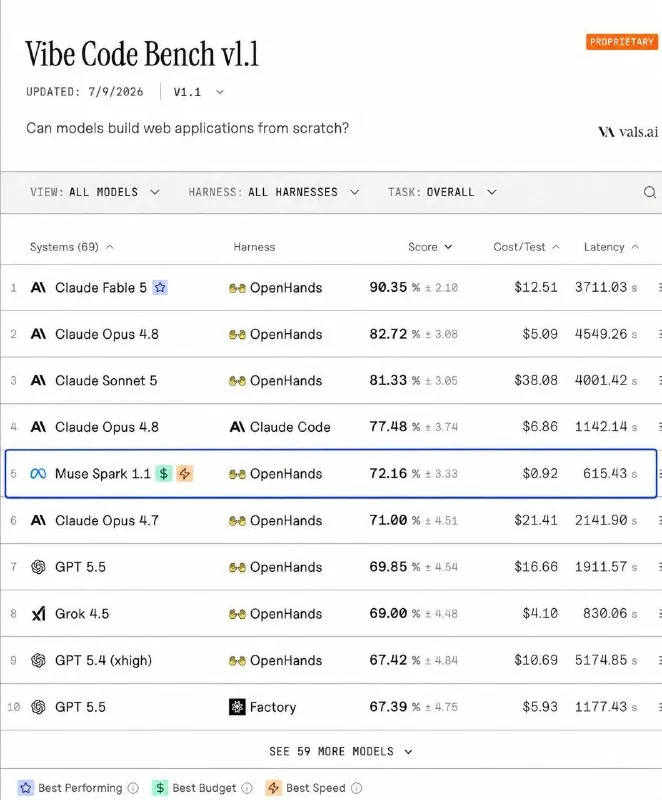
It also scored 72.16% on a web application programming benchmark, surpassing GPT-5.5, Grok 4.5, and GPT-5.4, but still trailing Fable 5 and several Claude models.