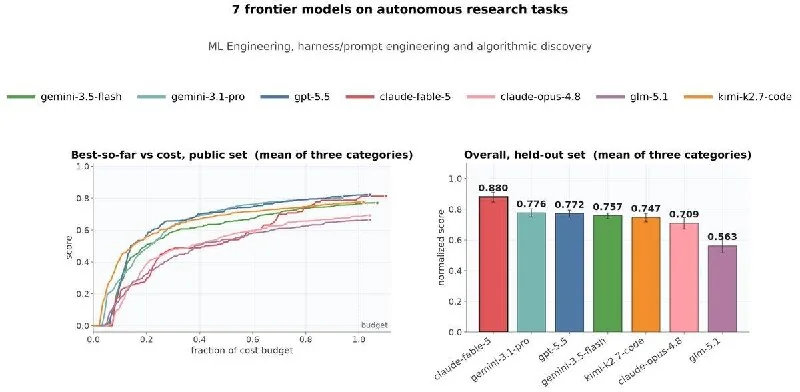
AI agent developer WecoAI has released benchmark results for seven frontier models on autonomous research tasks. In the machine learning engineering category, Moonshot AI's newly open-sourced trillion-parameter model, Kimi-K2.7-Code, beat every other model tested — including Anthropic's flagship Fable-5.
https://twitter.com/zhengyaojiang/status/2066213302921802194
The benchmark uses a cost-limited protocol (including model API and evaluation costs) rather than a step-limited one. That means cheaper models get more tries and iterations within a fixed budget. Overall, Fable-5 dominated in the test suite & prompt engineering and algorithm discovery categories, taking the overall crown. But in ML engineering, Fable-5 actually performed worse than its predecessor, Claude 3 Opus. WecoAI's team speculates that Fable-5's high API fees put it at a disadvantage under budget constraints, or that the task triggered more restrictive safety guardrails.