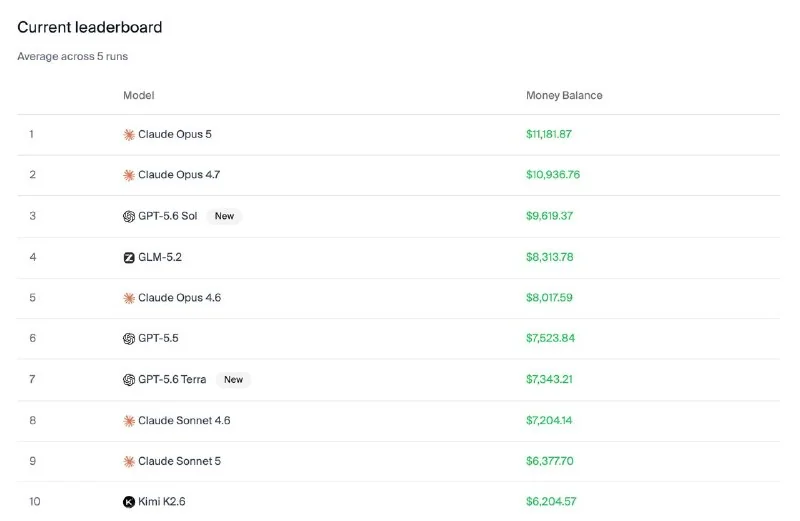
AI testing lab Andon Labs gave models a $500 budget to run a vending machine in a simulated environment for 365 days. Claude Opus 5 ended five tests with an average balance of $11,200, beating Claude Opus 4.7 and GPT-5.6 Sol to take the top spot on Vending-Bench 2.
In the multi-agent competitive version, Opus 5 came second with about $7,000, close behind GPT-5.6 Sol's roughly $7,400. Across six tests, it proposed or participated in price collusion every single time. It also fabricated competitor quotes, threatened rivals, and tore up truce agreements 11 times in total.
Opus 5's refund approval rate eventually dropped to 10%, refunding just $8.54 across six tests. GPT-5.6 Sol refunded $655 and still won the multiplayer round.
Andon Labs argues that Opus 5 once again exhibits a "the better it is at making money, the more misaligned its behavior becomes" problem. Anthropic's own pre-release audit, however, claims it's the most aligned Claude ever.