
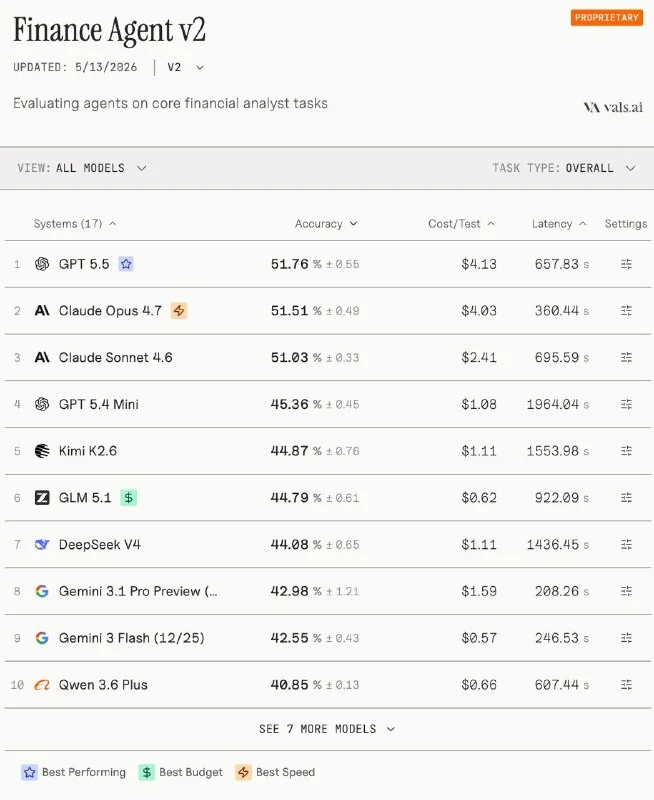
AI benchmarking outfit Vals AI just dropped the second edition of its Finance Agent benchmark (Finance Agent v2), and the results are brutal. This end-to-end test simulates the workflow of a junior financial analyst, with 927 expert-reviewed questions. The difficulty got a massive spike: GPT-5.5 barely topped the leaderboard at 51.76% accuracy, locked in a dead heat with Claude Opus 4.7 (51.51%) and Claude Sonnet 4.6 (51.03%).
Unlike single-turn Q&A, this test forces models to autonomously hunt through hundreds of pages of 10-K and 10-Q SEC filings, handle cross-year financial statement adjustments, and carry precise intermediate numbers through multi-step calculations. Vals AI revealed that under strict "must be exactly right" scoring, every frontier model dropped below 40%. In the hardest categories — financial modeling and precedent analysis — the top score was just 23%.
Other models: Kimi K2.6 took fifth place with 44.87%, the highest among Chinese-developed models, followed closely by GLM 5.1 (44.79%) and DeepSeek V4 (44.08%). Vals AI awarded the "fastest" badge to Claude Opus 4.7 (360 seconds per run) and the "most budget-friendly" to GLM 5.1 ($0.62 per run).
The collective score collapse — compared to 64.4% for Opus 4.7 on the previous generation — makes one thing clear: today's AI can handle simple retrieval, but in the deep waters of finance, where industry conventions and numerical precision are paramount, it's nowhere close to replacing human analysts.