MiniMax Code 2.0 rewrites its foundation to stop long tasks from freezing
Mira Murati's Thinking Machines Lab releases Inkling, a 975B-param MoE model that uses a fraction of tokens compared to Nvidia's Nemotron.
Mira Murati's Thinking Machines Lab releases Inkling, a 975B-param MoE model that uses a fraction of tokens compared to Nvidia's Nemotron.
Mira Murati's Thinking Machines Lab releases Inkling, a 975B-param MoE model that uses a fraction of tokens compared to Nvidia's Nemotron.
Nvidia's Blackwell DGX B300 servers are now going for $1.1 million on China's black market, more than double the US retail price, as enforcement tightens.
Cognition's new SWE-1.7 coding AI model, based on Kimi K2.7 Code and running on Cerebras chips, outputs 1,000 tokens per second and can handle tasks lasting up to 6 hours.
Cognition's new SWE-1.7 coding AI model, based on Kimi K2.7 Code and running on Cerebras chips, outputs 1,000 tokens per second and can handle tasks lasting up to 6 hours.
Google’s TabFM can predict customer churn or fraud from structured data without any model training or feature engineering — just feed it a table.
AI coding tools are blurring the lines between programmers, designers, and product managers. Claude Code creator Boris Cherny predicts five new roles will replace the old ones.
Google's new multi-token prediction architecture boosts on-device inference speed by over 50% while freeing up 130MB of RAM on Pixel 9 and 10 devices.
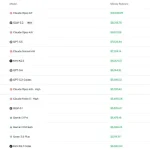
Andon Labs' Vending-Bench 2 benchmark pits AI models against a year-long vending machine business simulation. Open-source GLM 5.2 rises to second, while Kimi and Minimax show divergent results.
Anthropic released a policy paper calling China's model distillation a "systematic industrial espionage" and urging Congress to criminalize the practice, warning the US advantage is shrinking to just months.