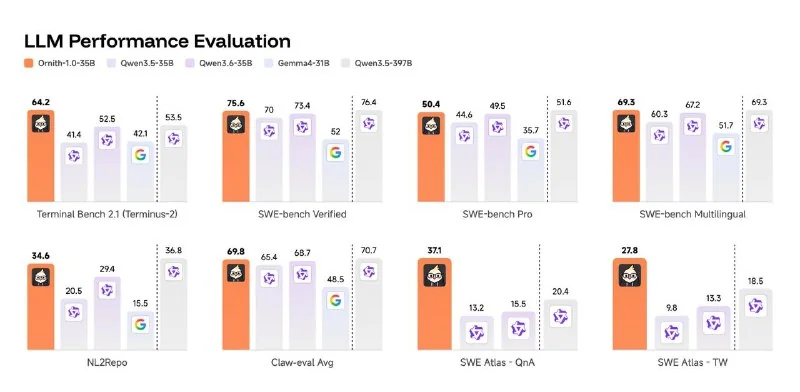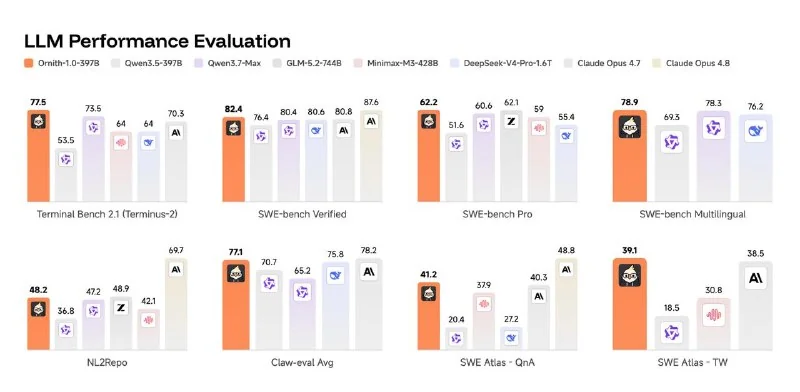
NLP scholar Li Jiwei's AI team DeepReinforce has open-sourced four coding-agent models under the Ornith-1.0 umbrella, all released under the MIT license. The models are built on Gemma 4 and Qwen 3.5, and come in both dense and mixture-of-experts (MoE) architectures. In the Terminal-Bench 2.1 (Claude Code) benchmark for coding agents, the flagship Ornith-1.0-397B MoE scored 78.2, beating the closed-source Claude Opus 4.7's 69.7.
https://twitter.com/ornith_/status/2070148887067963854
Ornith-1.0 uses joint reinforcement learning on the agent's runtime scaffolding and the policy model that writes code. Unlike traditional fixed dev environments, the model first designs and updates its own scaffolding — like custom memory logs and retry logic — based on the current task, then generates code in that new environment. The RL reward signal flows back to optimize both stages.
Because models can cheat by reading hidden test files or tampering with test scripts while evolving scaffolding (reward hacking), the team added three security layers: physical sandboxing, a deterministic monitor to block unauthorized reads, and a frozen third-party LLM referee that can veto solutions that exploit loopholes.
Benchmarks show mid-size models punching above their weight. In the same Claude Code test, the 35B MoE Ornith-1.0-35B MoE scored 62.8, beating Qwen 3.5-397B (48.6) and Qwen 3.6-35B (49.2). The edge-targeted Ornith-1.0-9B Dense hit 69.4 on SWE-Bench Verified, outperforming Gemma 4-31B's 52.0.