DeepSeek launches vision mode with spatial reasoning — and a mysterious pull
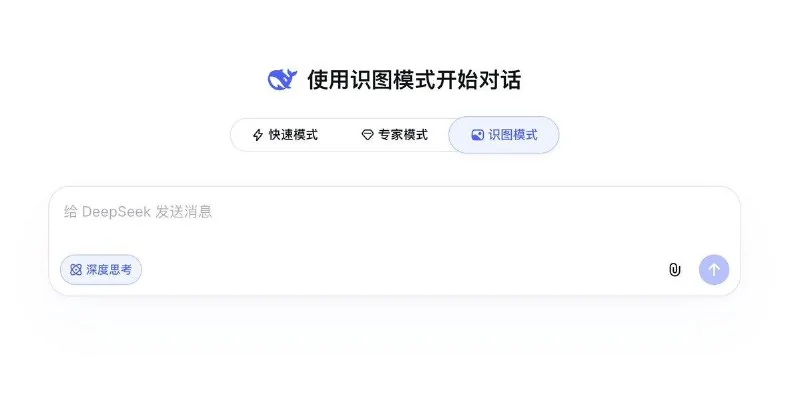
DeepSeek's web and app versions now offer a Vision Mode, sitting alongside Quick Mode and Expert Mode above the chat input. This isn't just OCR — it's built for deep scene analysis, spatial logic, and turning UI screenshots straight into HTML structure. When faced with tough geometry or complex charts, the system kicks in a deep-thinking model and shows you the full reasoning chain.
https://twitter.com/PKUCXK/status/2067460570958426452
Under the hood, the Vision Mode relies on a framework DeepSeek calls "Thinking with Visual Primitives." In a paper co-authored by multimodal researcher Xiaokang Chen, along with teams from Peking and Tsinghua universities, they point out a "Reference Gap" in current vision-language models: these models struggle to describe precise visual coordinates with fuzzy natural language. So the team elevated coordinate points and bounding boxes to the smallest units of thought, inserting spatial primitives directly into the model's chain-of-thought reasoning — letting it point and think at the same time.
The academic paper and open-source project that form the basis of this vision capability were briefly released on April 30, then yanked without warning by DeepSeek on May 1, sparking industry chatter about oversharing technical details and what might come next. As it stands, the Vision Mode handles images only — no video, no audio, and no image generation.